Cotex / Kalbim Duracak
Animated music video. Script, direction, animation, rendering, editing, and compositing.
Projects / Prototypes
Selected work
Independent Unity tool developed from a Scene-editable procedural shape into a system for UI and 3D scene rendering, runtime control, and reusable authoring workflows.
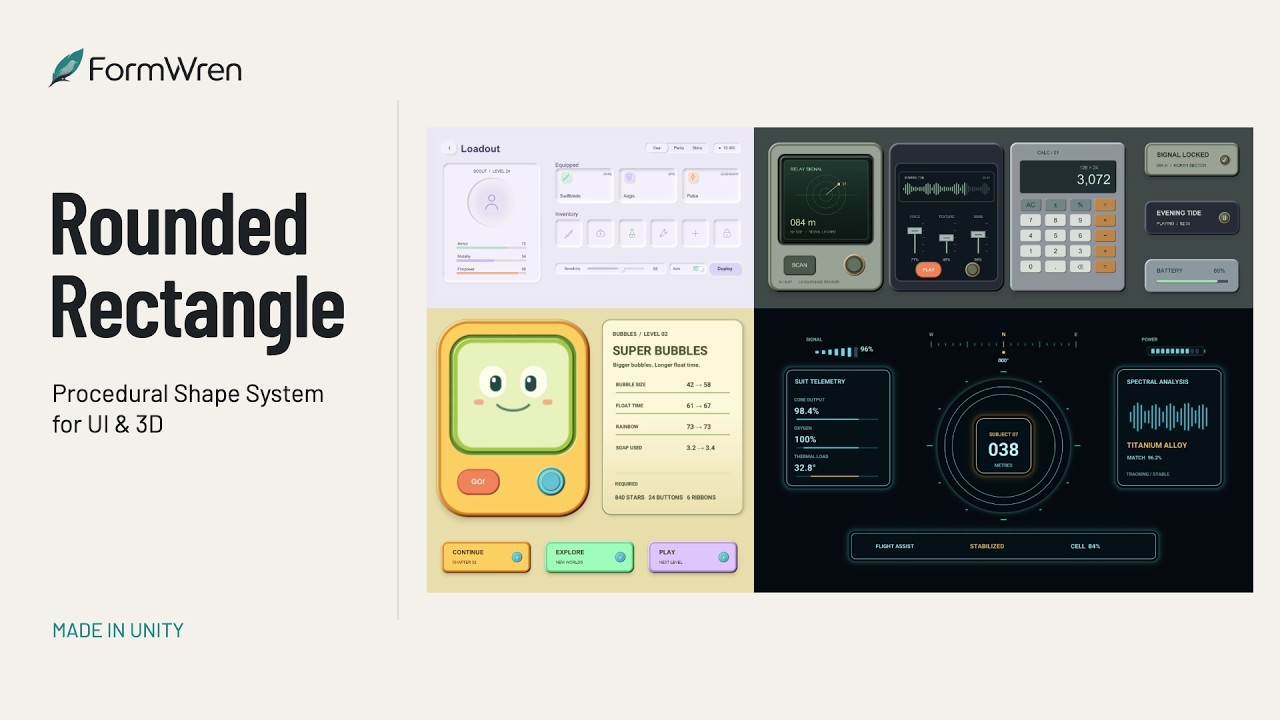 Trailer
Watch trailer and read development note ->
Browser-based experiments in soft lattice bodies, local control, and causally inspected movement.
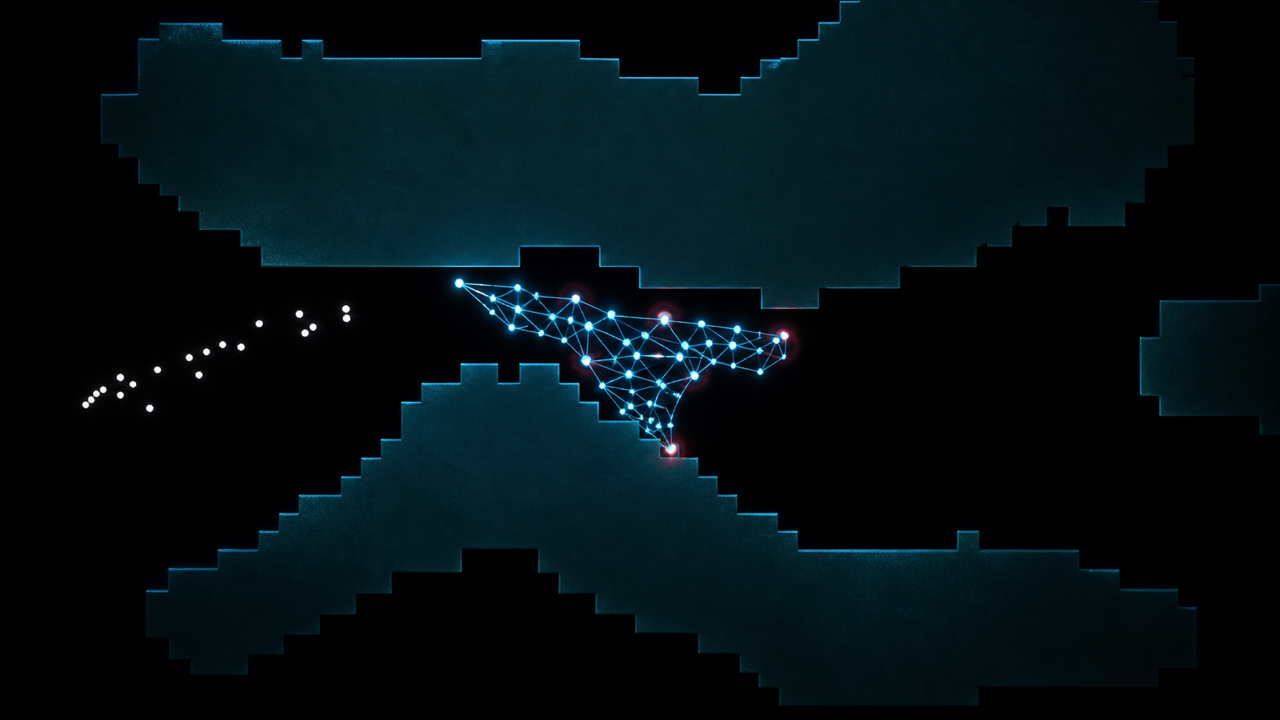 Active independent work. Read project note ->
Medical software company I co-founded through TÜBİTAK 1812 BiGG and developed at İTÜ ARI Teknokent. The work includes DICOM visualization, 3D interaction, and patient-specific design.
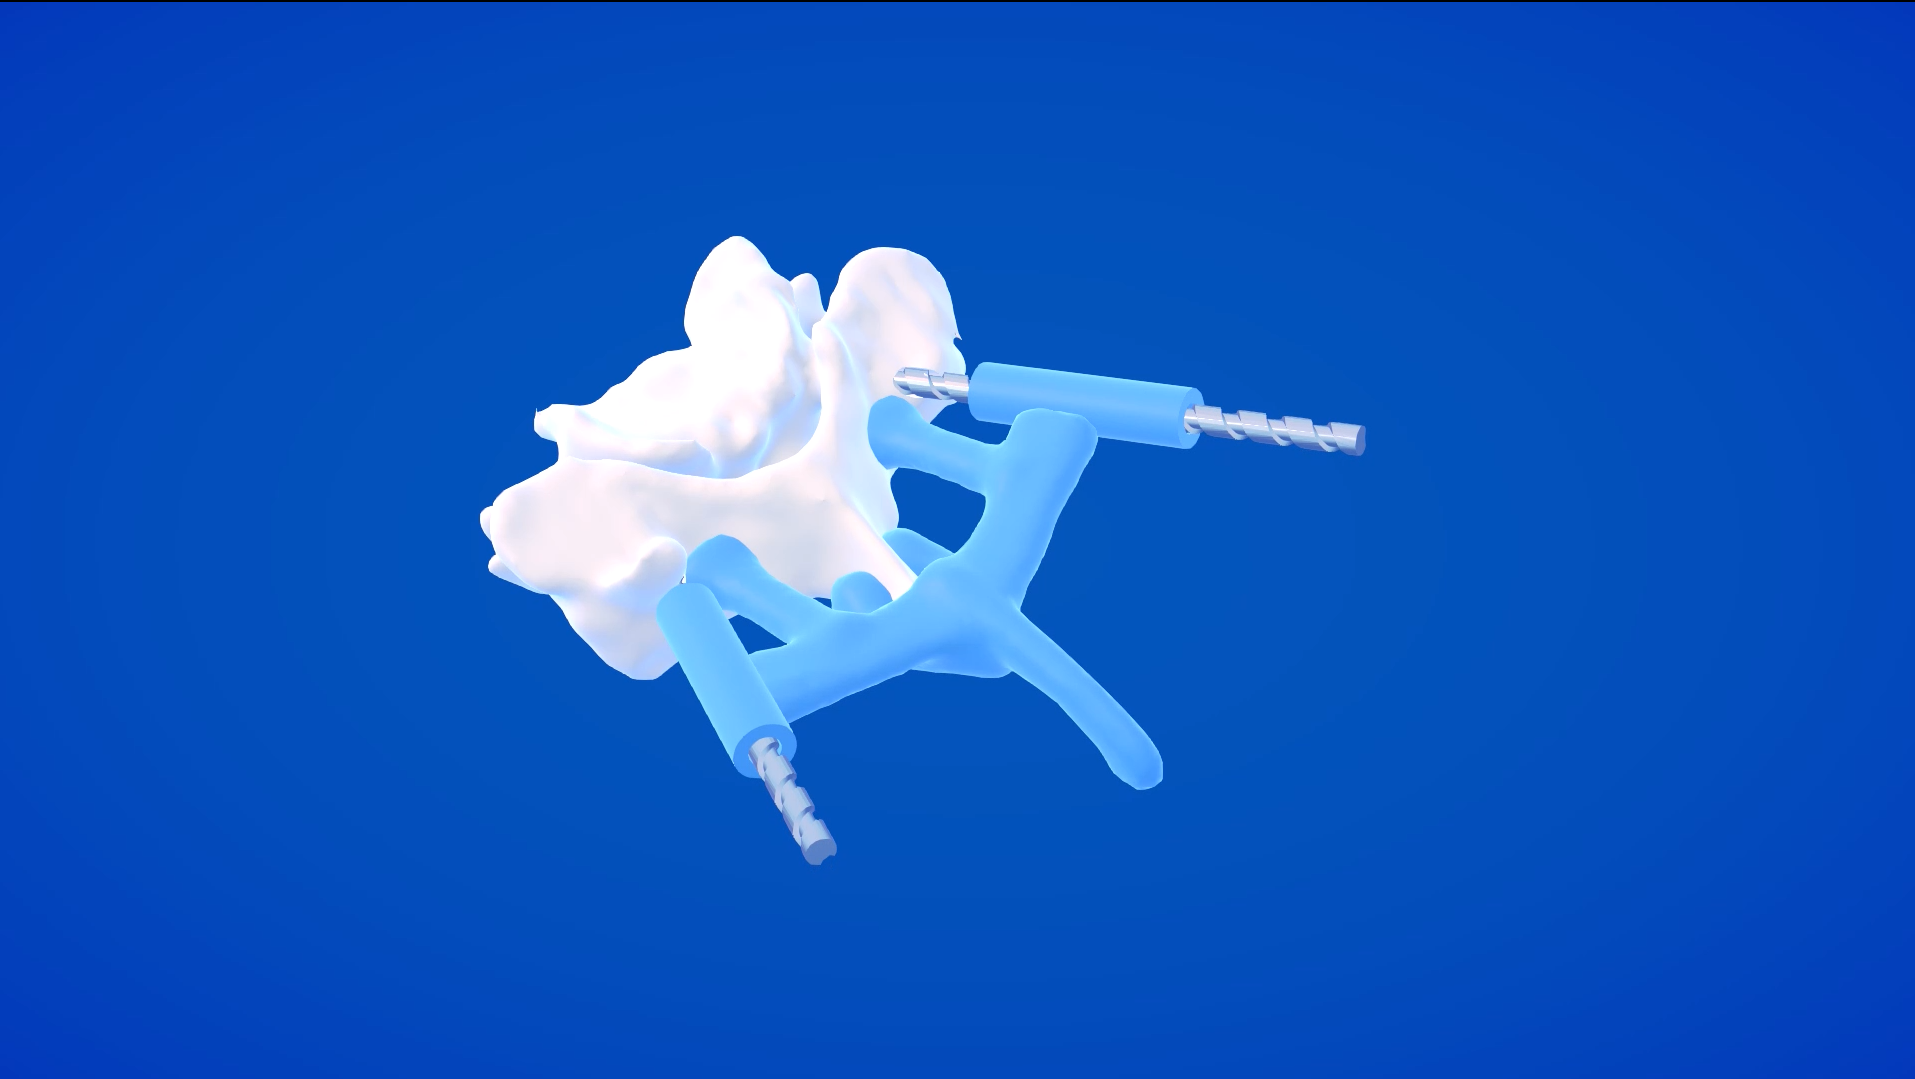 Company and project note ->
A word puzzle built around interlocking word and shape clues, where each placed piece gradually opens up the board. I developed the original concept and now work on its ad creative video and playable production.
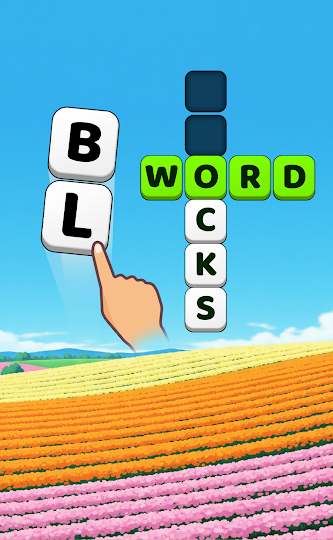
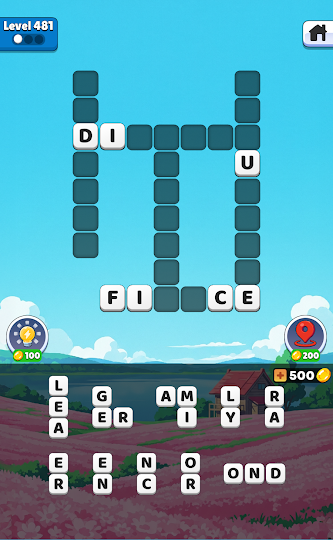
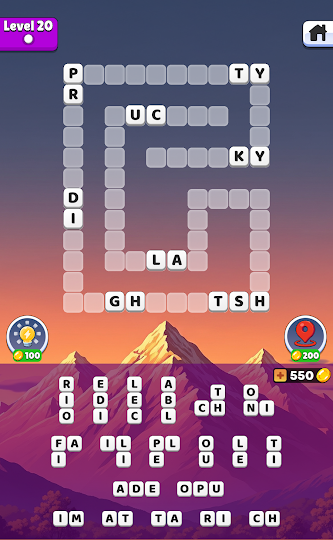 Current creative production work. Read project note ->
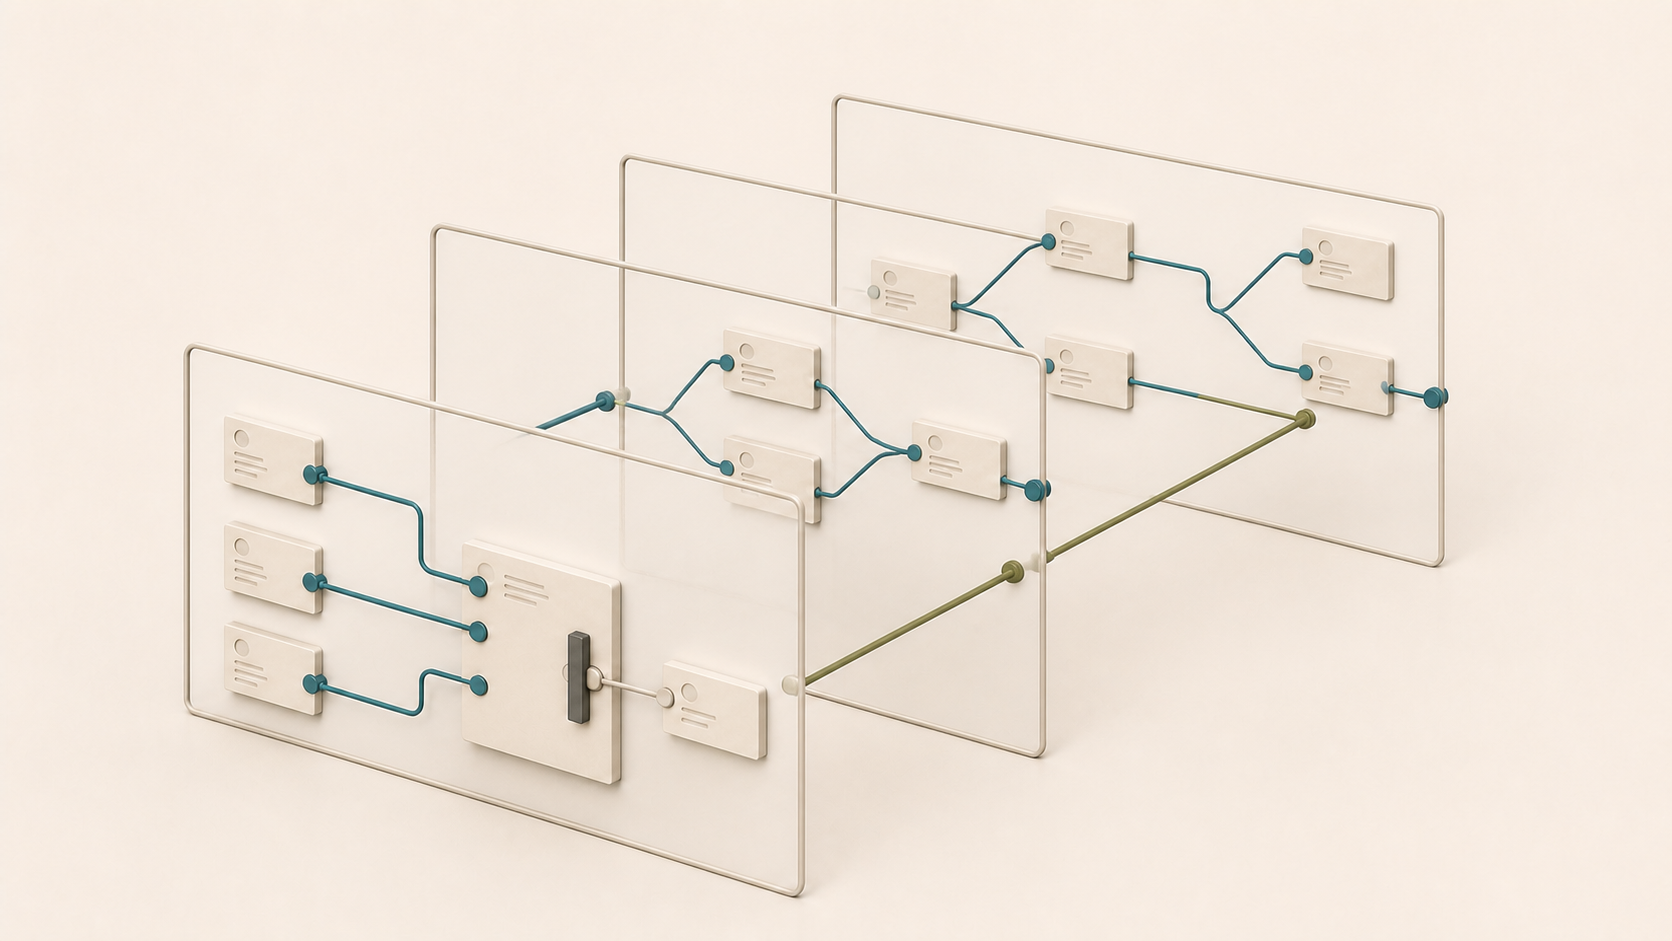
A local graph-backed system I use to keep tasks, project context, research, decisions, and agent handoffs connected across different projects.
 Active internal system. Read project note ->
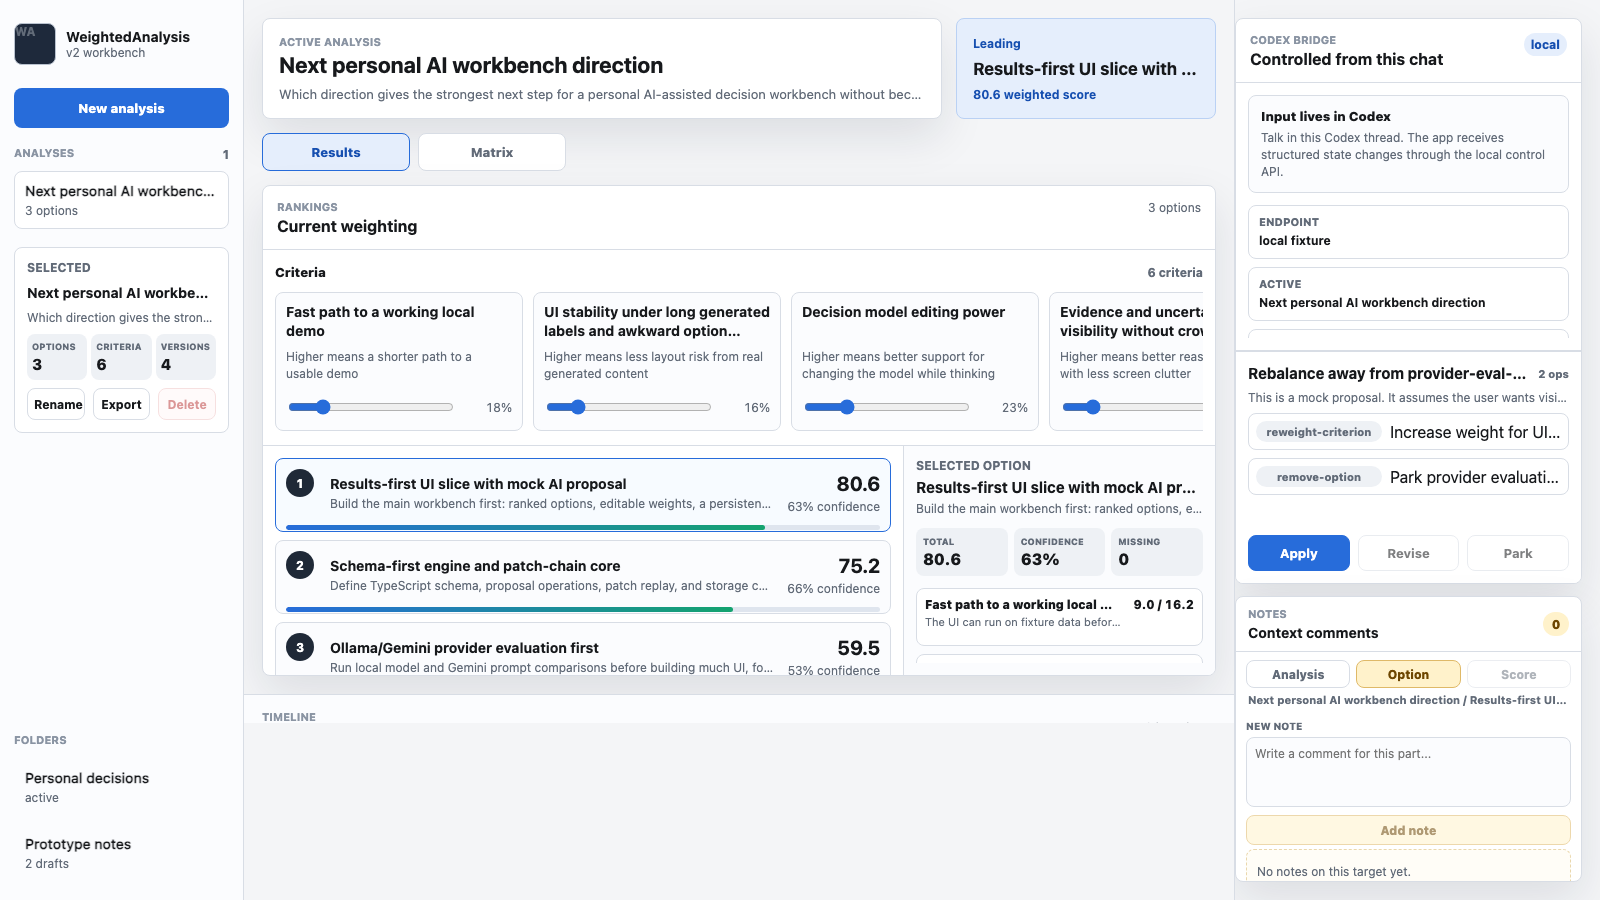
A local decision workbench for comparing options through editable criteria, weights, scores, evidence, uncertainty, and staged analyses.
 Active application. Read project note ->
Games
No-Pact / 2014
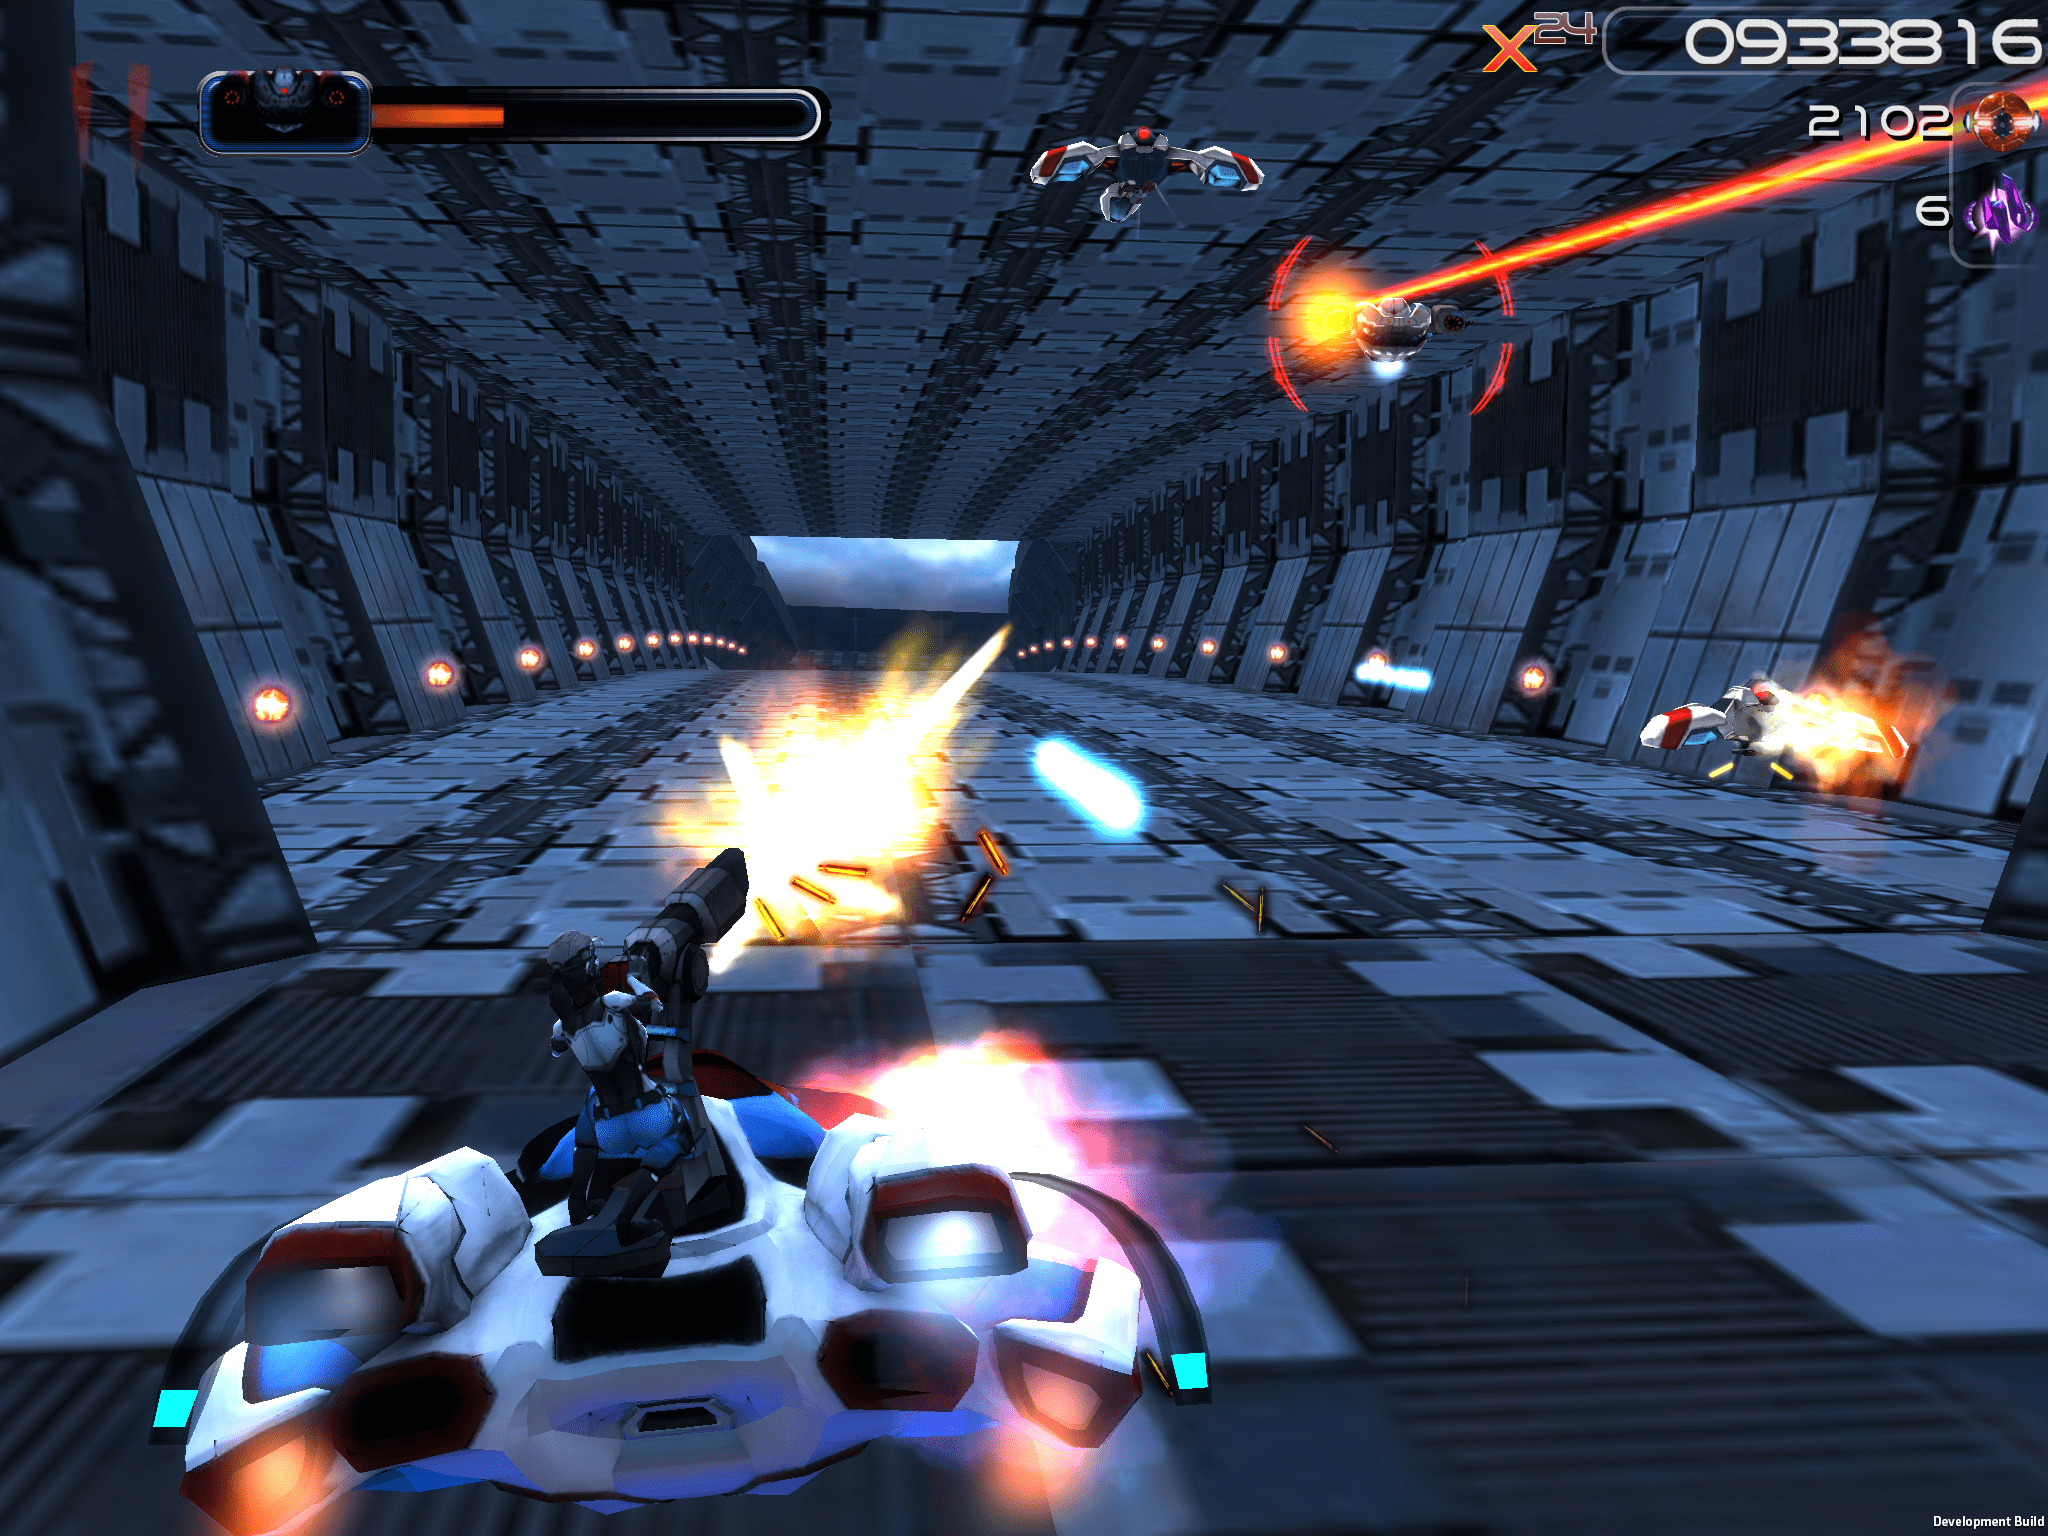
iPhone and iPad action game made at No-Pact, the independent game studio I co-founded. I worked on the visual direction, game design, Unity prototyping, controls, combat, UI, VFX, enemies, characters, and overall game feel.
 Project page and public release material ->
No-Pact / 2021-2022
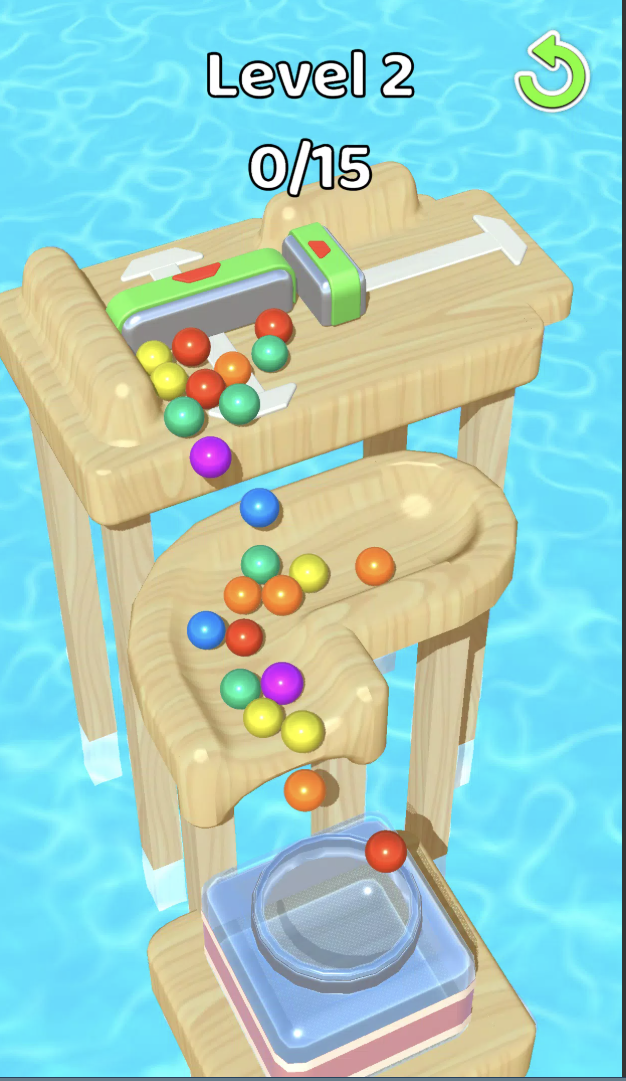
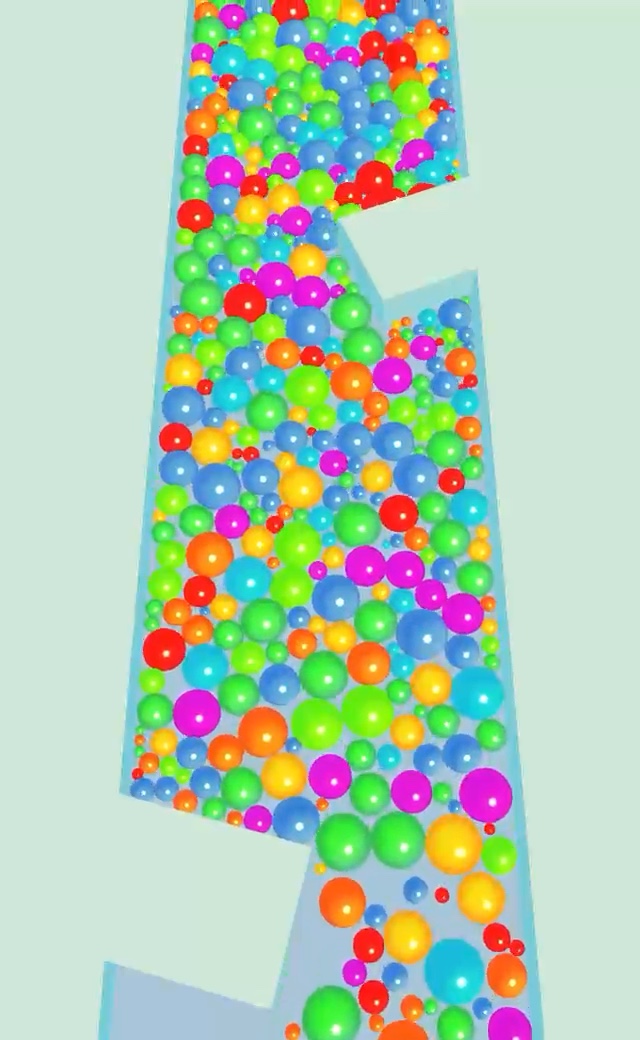
A Unity physics-puzzle prototype built around sequencing sweepers and other mechanisms to move groups of balls through compact levels. I directed the project and worked on gameplay and visual design, the level system and individual levels, physics and mechanics, difficulty progression, and VFX.
 Mobile physics prototype. Read project note ->
No-Pact / Mobile game development
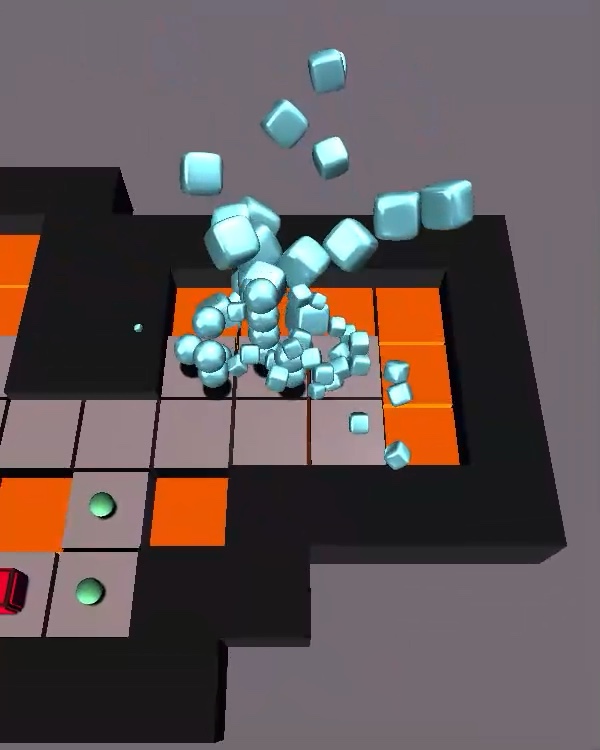
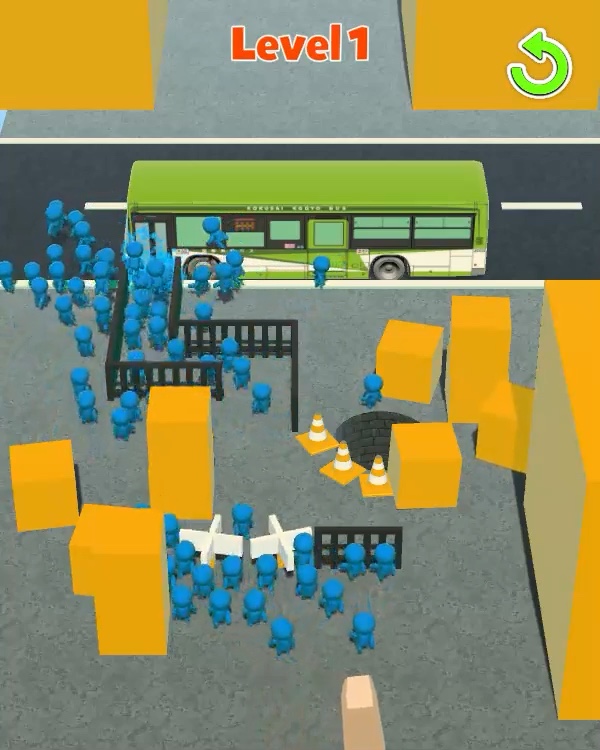
Small Unity builds made to test controls, physics, cameras, procedural behavior, and combinations of familiar mechanics.
 Read prototyping note ->
No-Pact / 2022
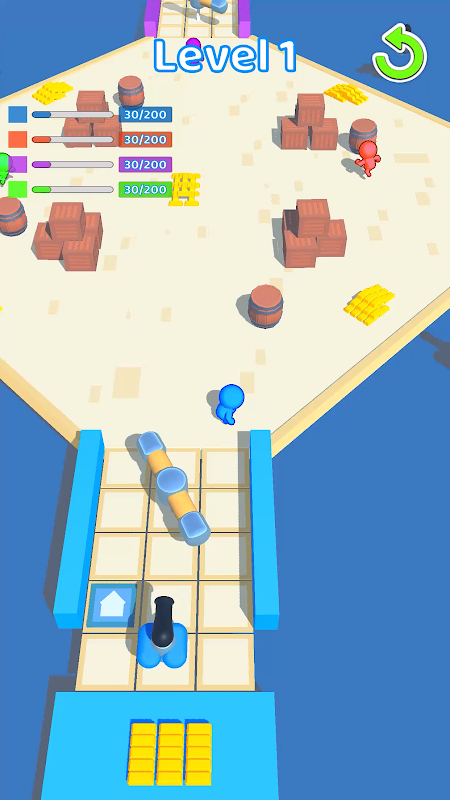
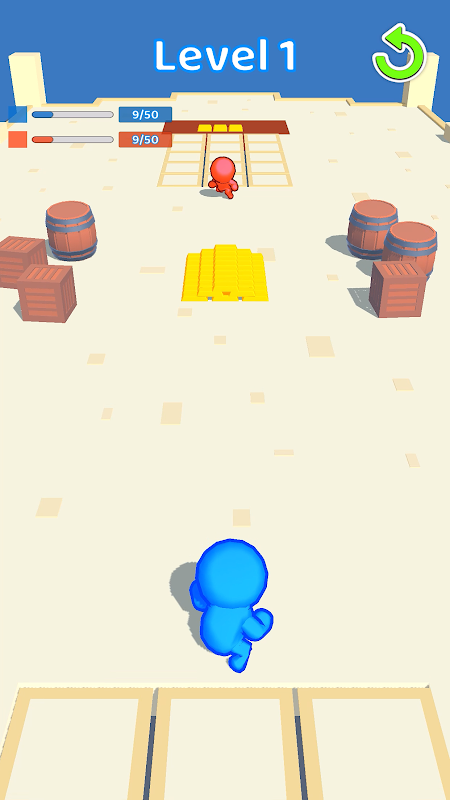
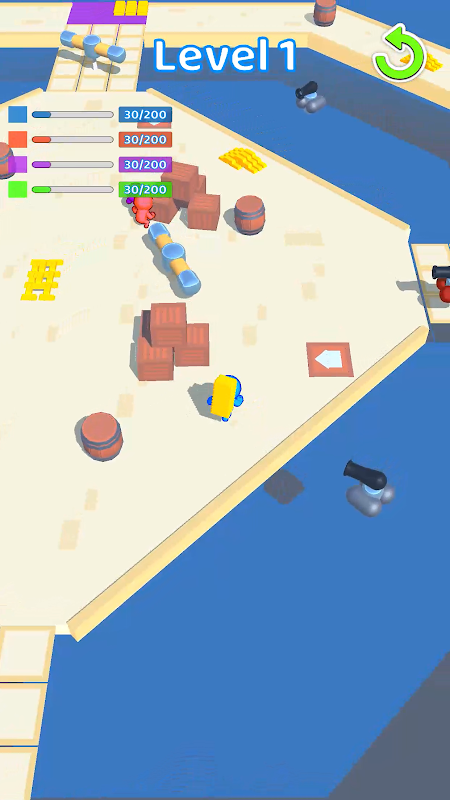
A competitive Unity arena prototype built around preparing a base, stealing gold from AI rivals, and deciding when to risk a larger carried stack. I developed the concept and worked on game and level design, visual implementation, Unity tuning, and build review.
 Mobile arena prototype. Read project note ->
No-Pact / Early VR
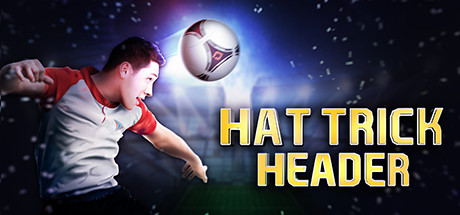
A head-controlled football game concept and playable VR prototype I developed during the Oculus DK2 period. No-Pact later developed and released the game on Steam.
 Prototype and release note ->
Archive
Animated music video. Script, direction, animation, rendering, editing, and compositing.
3D and compositing work for Akbank, Hayat Su, Crunch, Pegasus, and other commercial productions.
Weekly animation production: character work, rigging, animation, lighting, materials, rendering, and delivery.
Student internship during post-production, creating animated mask and matte sequences for effects shots.
 Feature-film project context.
About
I design and build interactive software, from game prototypes and production tools to medical visualization and simulation. My background combines visual design, animation and game development. I integrate AI agents into my research, design and development workflows, guiding the work through experimentation, testing and iteration. I co-founded No-Pact and Orbycra, and develop independent tools under FormWren.
Games / No-Pact / 2014
iPhone and iPad action game.
The game
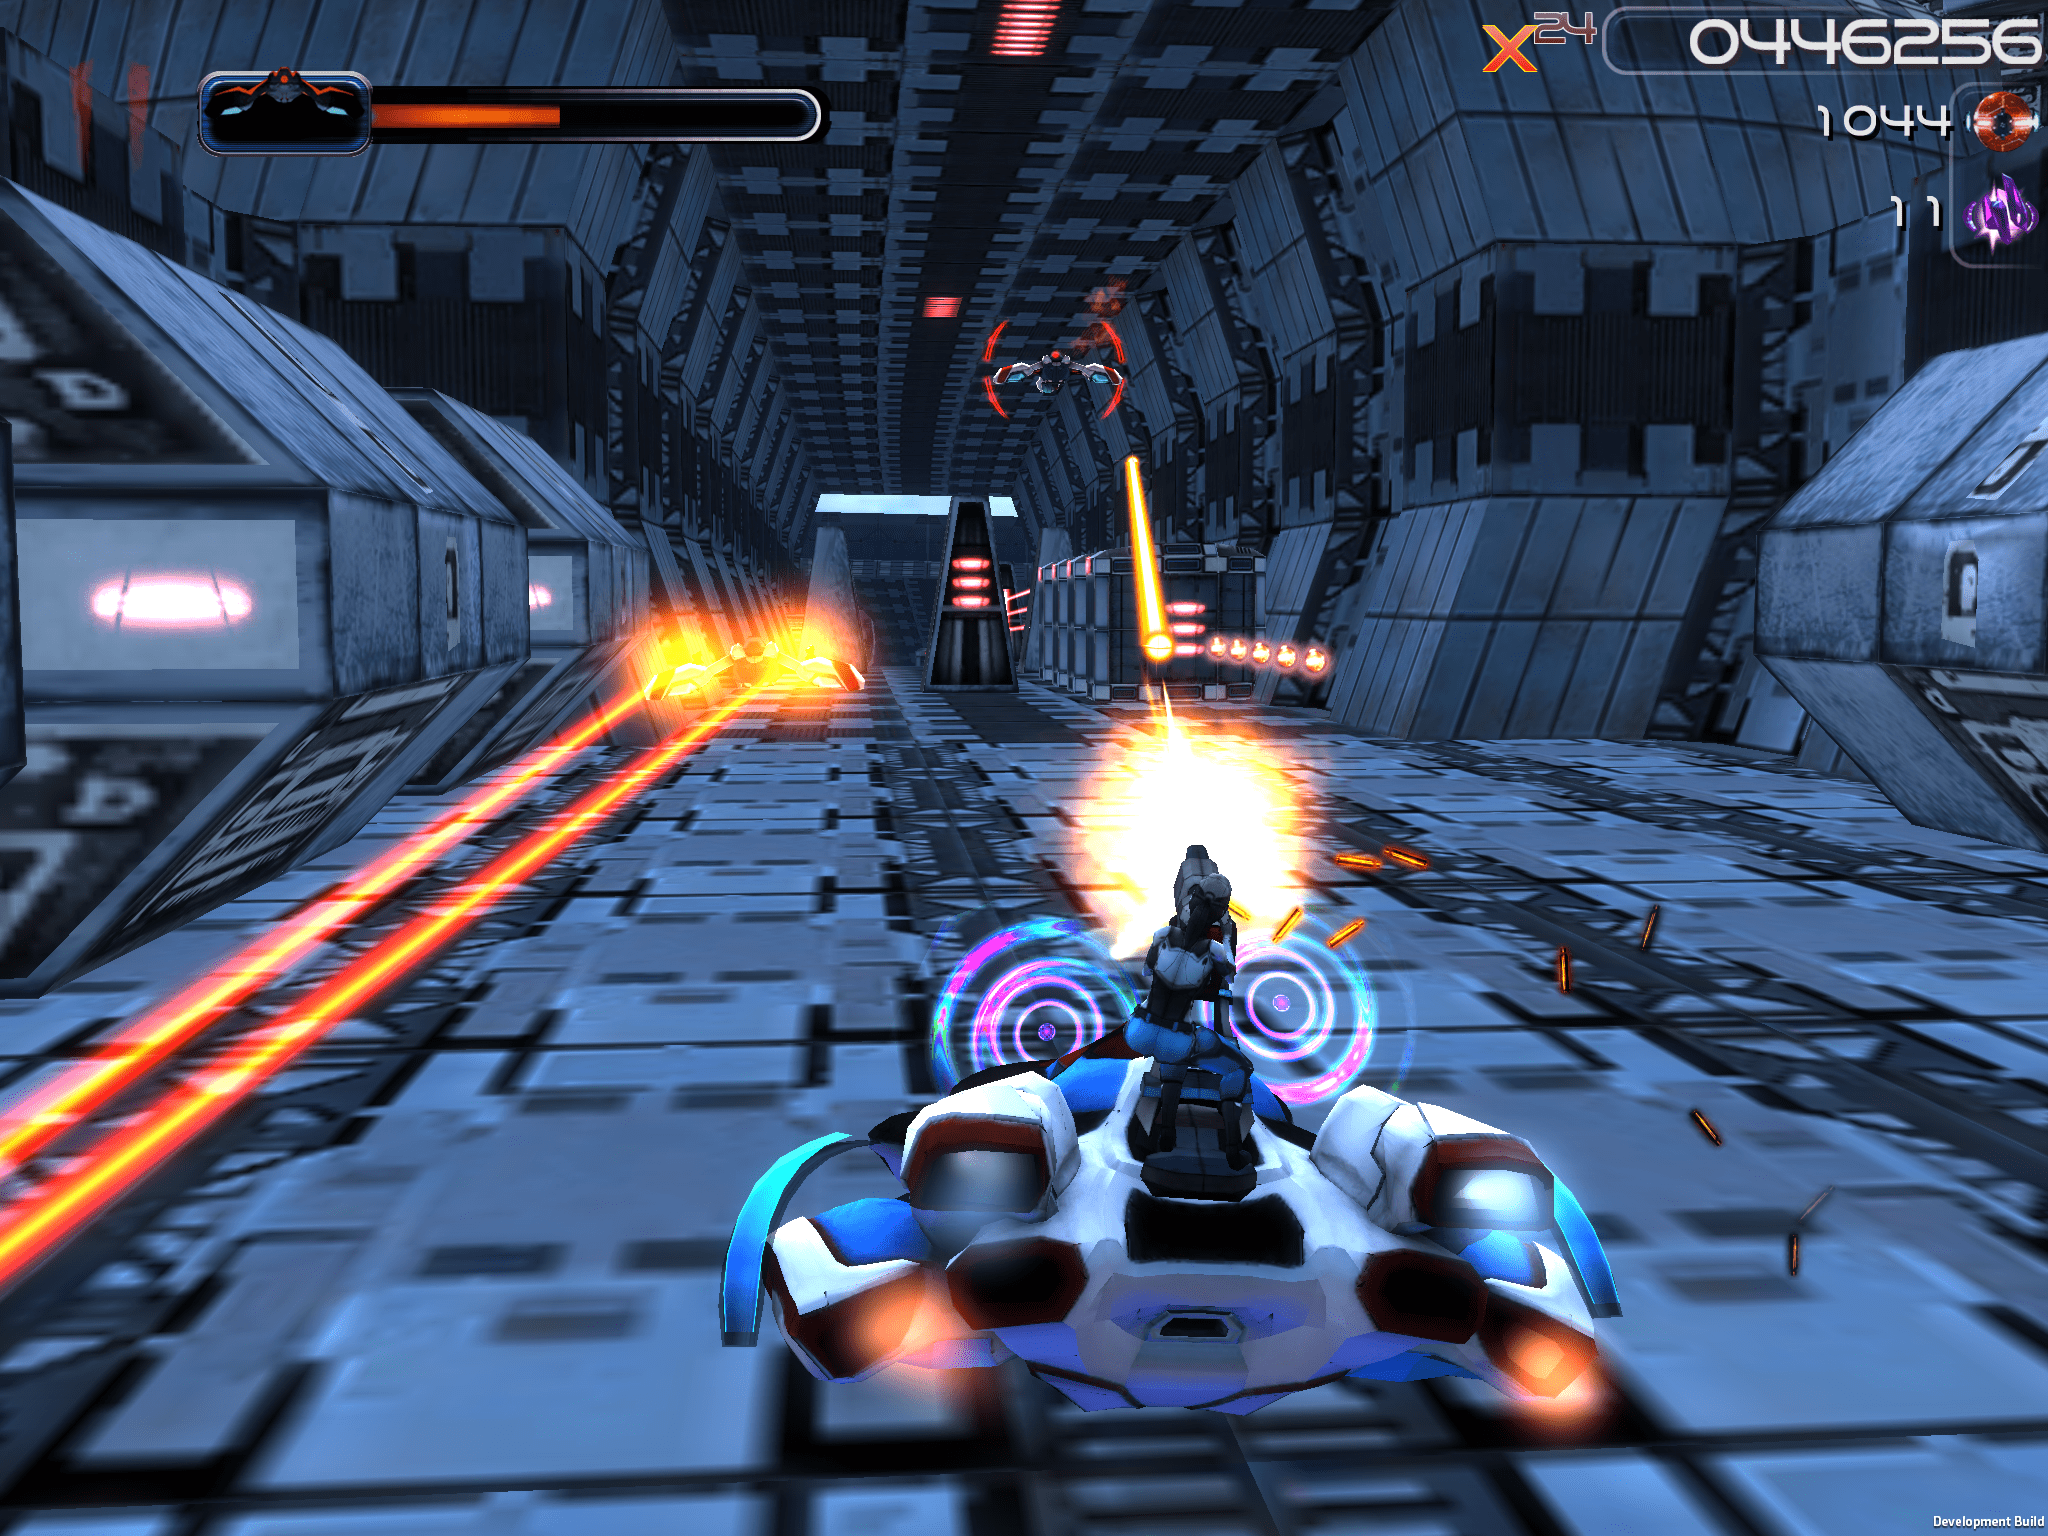
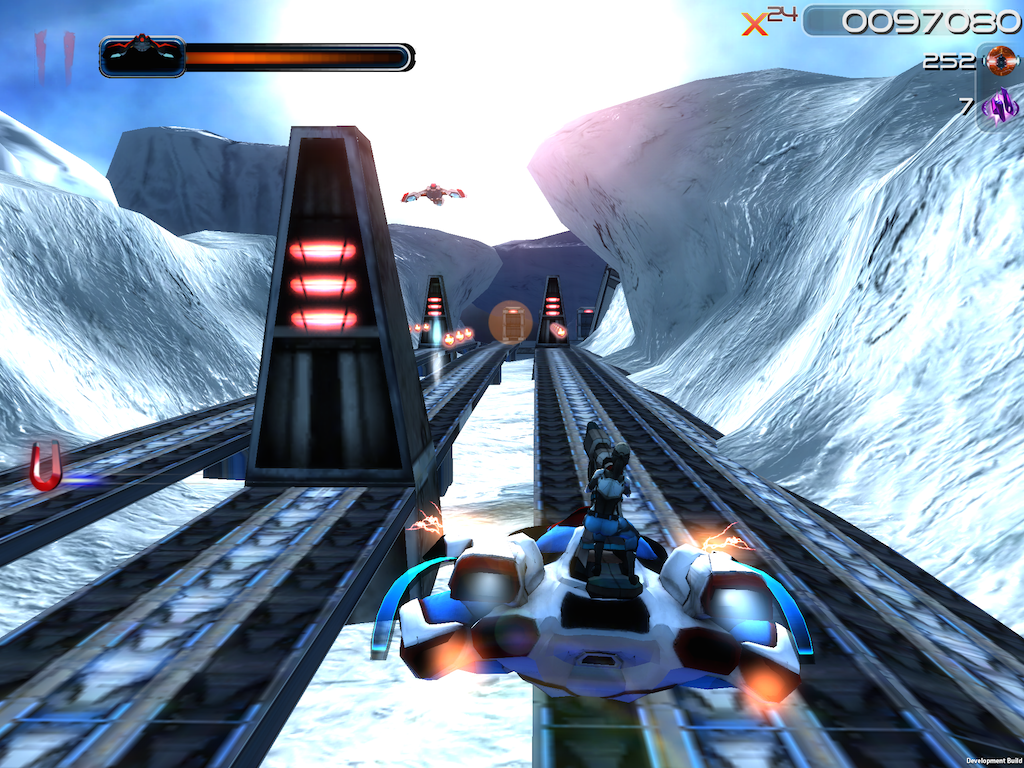
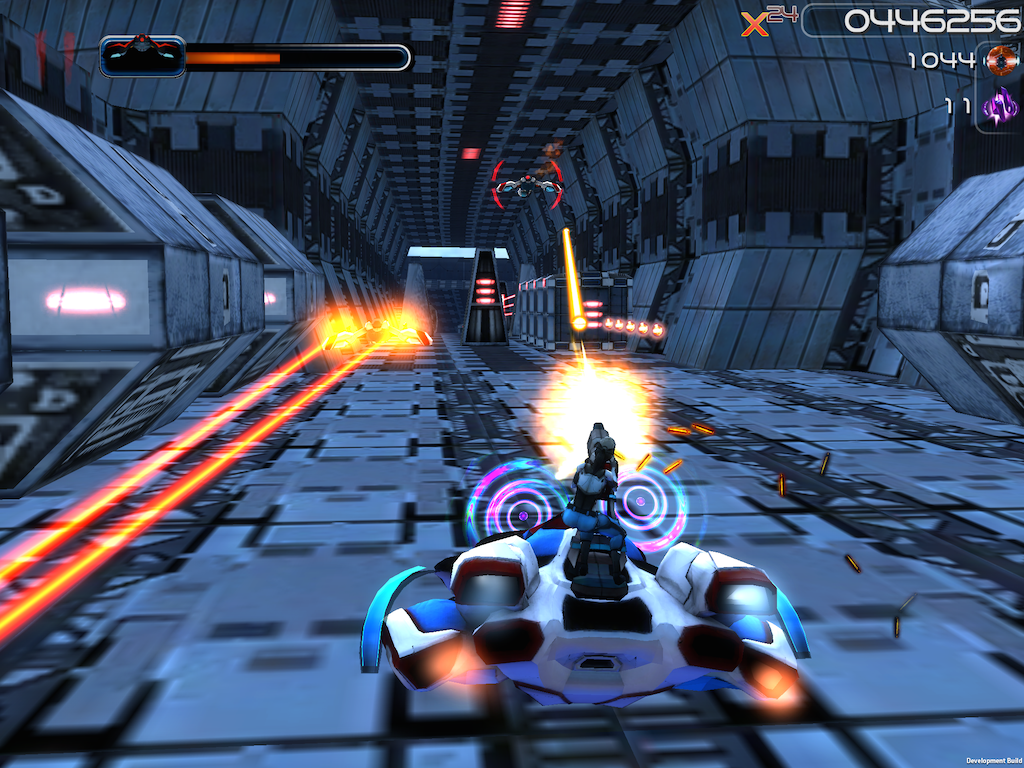
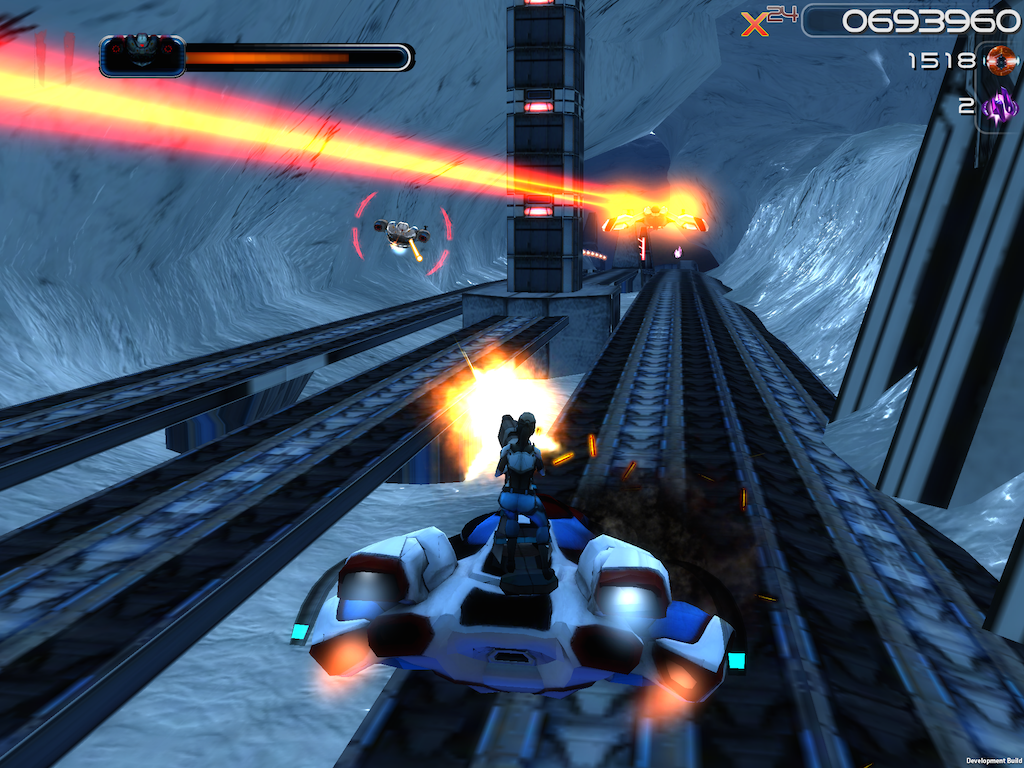
Reclaim was the first game from No-Pact, the small independent studio I co-founded. Released for iPhone and iPad in 2014, it combined lane-based movement, shooting, upgrades, and continuous mission play in a science-fiction action game.
The player steers a gunship through obstacle-filled routes, moves between lanes, fires a cannon, and uses a mounted gatling gun while avoiding and attacking enemy robots.
My contribution
Ship, characters, enemies, environments, assets, animation, VFX, and the overall game presentation.
I designed the complete in-game interface, the Reclaim logo, and the visual material prepared for its App Store release.
Core controls, weapons, combat rhythm, movement dynamics, and player feedback.
Early gameplay prototypes used Unity, C# scripting, and physics-based interaction work to establish control and combat feel.
I worked with engineers as the mechanics, tests, visuals, and game systems came together. The engineering team later refined or rewrote production implementations where needed.
Seamless terrain mesh sets for procedural level assembly, including multiple levels of detail, textures, shaders, and mobile performance work.
Combat encounters and level obstacles adjusted to player performance, keeping the generated routes challenging as player skill changed.
A coordinated rig for the moving ship, mounted turret, and character, using inverse kinematics and blended animation while aiming and firing.
An automatic camera system that followed movement and reframed the ship, route, and nearby action as the situation changed.
I produced the Reclaim trailer over roughly one month using the game's assets and Maya's hardware renderer. The work covered the concept and script, shot production, animation and rendering, and final edit.
Gameplay and screenshots
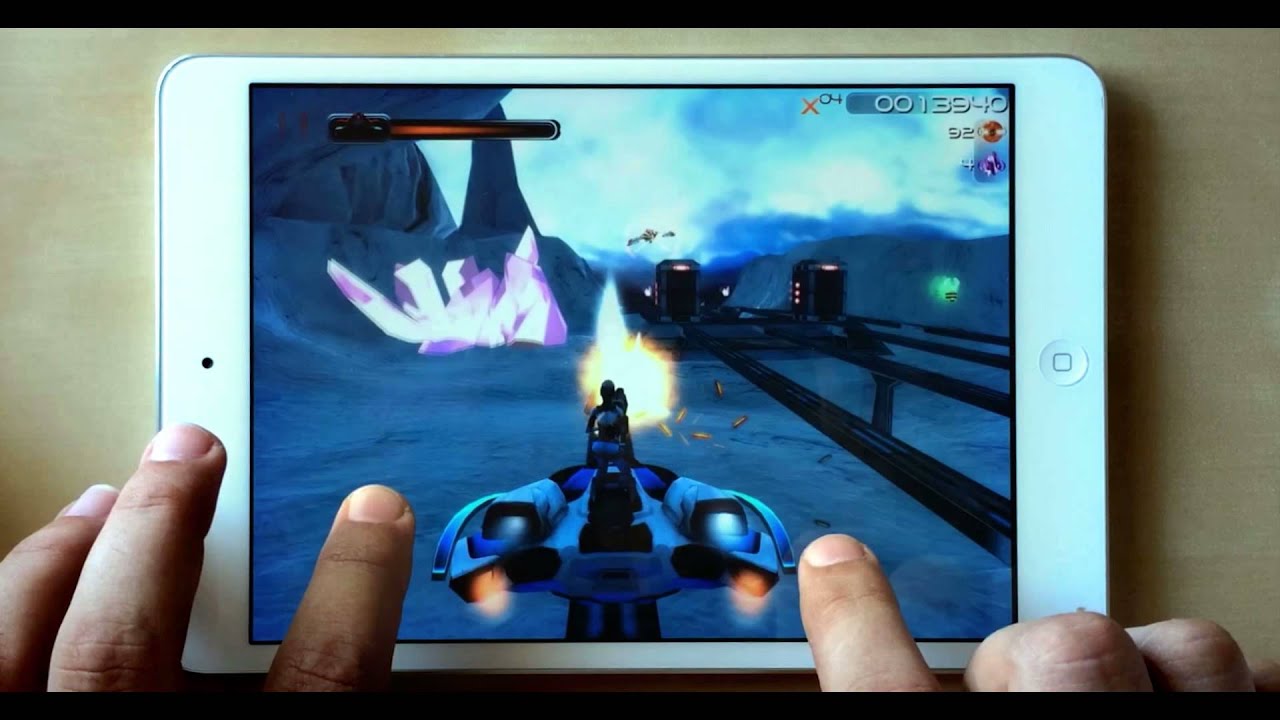 Gameplay video ->
Game concept / Creative production
Original core-loop concept, followed later by ad creative video and playable production work.
The project
Word Blocks began during an intensive period of mobile game ideation and Unity prototyping at No-Pact, the independent game studio I had co-founded. I developed the original core-loop idea and made a simple animation to communicate it to the team.
After that concept handoff, I was not involved in the game's subsequent production. I returned after the game had gained traction, taking over ad creative production and later developing related workflows for video and playable ads.
Available now
Word Blocks is available on the App Store and Google Play. These current store screenshots show the released game; the sections below describe my original concept work and the creative-production work I later returned to.


Words and shapes as clues
The board gives the player two kinds of information at once: incomplete words and the shapes of the spaces they occupy. Familiar block-puzzle pieces complete several words as they are fitted into the board.
Each placement reduces both the word puzzle and the remaining spatial problem. A dense board gradually opens up and becomes easier to read, giving the solve a visible sense of release.
The same visual structure is also legible in short video: familiar block shapes, a crossword-like board, and progress that can be understood within a few seconds.
After returning to the project
Unity tools for preparing authored gameplay, recording repeatable interactions, and reviewing how a solve reads in a short video.
Different hooks, board arrangements, palettes, backgrounds, layouts, timing, and end treatments built around recognizable game behavior.
Repeatable rendering, named variants, format checks, contact sheets, and delivery preparation for producing and reviewing groups of videos.
A related lightweight HTML workflow that uses Unity-authored levels and creative structure to produce versioned, browser-tested playable variants.
No-Pact / Mobile game development
Small Unity builds used to examine a control, a behavior, or a game idea before deciding what deserved more work.
The work
At No-Pact I moved between idea sessions, reference study, and short Unity builds. The surviving material includes weekly idea notes, catalogs of controls and mechanics, design generators, dated build logs, scripts, and recordings of playable scenes.
Those records do not mean that every written idea became a prototype. I kept the distinction deliberately: some directions stayed as notes, while others became working scenes that could be played, watched, and compared. This page concentrates on the second group and on the work that led to them.
Working cycle
The starting point varied. I might notice a useful control or camera structure in another game, separate a mechanic into parts, combine two familiar forms, use a generated constraint, or begin directly in Unity with a movement or physics question.
The cycle was usually short: isolate the question, build the smallest scene that could answer it, record or share the result, then continue, rework, or stop. The dated work log moves back and forth between idea generation, market review, scene setup, and playable builds rather than treating them as separate phases.
Recorded Unity builds
Ways of finding and testing ideas
I tracked controls, cameras, mechanics, visual formats, and recurring structures in existing games, then separated the parts that could be examined or recombined.
I described games through dimensions such as camera, world, movement, goals, controls, feeling, readability, depth, and production cost. Random combinations were starting constraints, not answers.
Most questions were answered with the smallest useful scene: one control, one rig, one camera, one interaction, or one procedural behavior.
Early text-completion tools offered another source of prompts: I could begin an unfinished game description and inspect the branches suggested by its continuation. The output was material for exploration, not a design by itself.
Beyond the short test
No-Pact / Mobile prototype / 2021-2022
A physics puzzle about triggering mechanisms in the right sequence to move groups of balls through compact levels.
Team prototype
Ball Sweep was developed at No-Pact as a mobile physics-puzzle prototype. Each level arranged groups of balls, sweepers, platforms, and a collection target into a compact chain of physical actions. The player had to read the route, trigger mechanisms in a useful order, and deliver enough balls without losing them along the way.
The project grew beyond an initial mechanic test into a large level-design and review process. The working notes cover level ordering, tutorials, camera transitions, aspect-ratio framing, physics failure cases, difficulty, visual clarity, and recordings prepared to compare different level and presentation choices.
Level loop
The level presents groups of balls, mechanisms, obstacles, and the collection target as one compact physical layout.
Sweepers and other devices are activated in a useful order and at the right moment.
Poor timing can send balls off the route, leave them behind, or make the remaining sequence harder to complete.
The level is completed by delivering the required number of balls to the collection point.
My contribution
Directed the prototype's development and shaped its core loop, interaction rules, gameplay feel, and priorities for each iteration.
Designed the reusable level structure and individual levels, introducing mechanics and physical situations through a deliberate difficulty progression.
Developed and tuned ball behavior, sweepers, obstacles, and collection rules so their interactions remained readable and responsive across repeated play.
Established the prototype's visual language and created effects, camera framing, and feedback that clarified movement, hazards, interactions, and outcomes.
Selected prototype evidence
No-Pact / Mobile prototype / 2022
A competitive arena prototype connecting base preparation with stealing, carrying, and securing gold.
Team prototype
Thieves.io was developed at No-Pact as a top-down Unity arena prototype. I developed the original concept and worked with a programmer as it grew from a first playable into a working game with multiple internal builds.
Each round connected two kinds of play. The player first arranged defenses and obstacles around a base, then entered an arena against AI rivals to collect or steal gold and carry it home. A larger stack represented more progress, but it also made every collision, trap, and risky route more consequential.
Round structure
Place a small set of defenses or obstacles such as rotating arms, turrets, blocks, and launching platforms.
Move through the level with joystick control while one to three AI rivals pursue the same gold target.
Collect loose gold or take it from rival bases. The carried stack stays visible and can be scattered through collisions and hazards.
Return gold to the base before a rival reaches the target, while using routes, defenses, and physical interactions to interfere with opponents.
My contribution
The two-phase premise, gold-stealing loop, base preparation, interaction rules, first-playable scope, and questions about how preparation should affect arena play.
Base visibility, encounter frequency, routes, hazards, trap placement, one-versus-one and multi-rival layouts, and situations that could create deliberate risk or tactical play.
Color coding, materials, gold and environment treatment, 3D props, turret and launcher readability, firing and impact effects, and direct work in the prototype scenes.
Movement and collision values, gold scatter, turret force, camera and screen-ratio checks, repeated build testing, bug reproduction, fix priorities, and structured feedback questions.
Builds v0.1.100-v0.1.107
Four bases, simple AI thieves, gold carrying, preparation and arena phases, turrets, rotating obstacles, launchers, collisions, and several win or fail conditions.
Friendly-fire behavior, restart persistence, win conditions, gold loss, pathfinding, aspect-ratio-aware cameras, and safer introductory levels were revised after early reviews.
Adjustable AI and respawn behavior, collision rules, a joystick-tuning menu, wider arenas, and one-versus-one tests were used to make outcomes more readable and less arbitrary.
Later reviews separated gold collection, rivals, defenses, hazards, launching platforms, and additional opponents into a more deliberate teaching order.
Android release archive
Games / No-Pact / Early VR
A football prototype controlled through headset movement.
The project
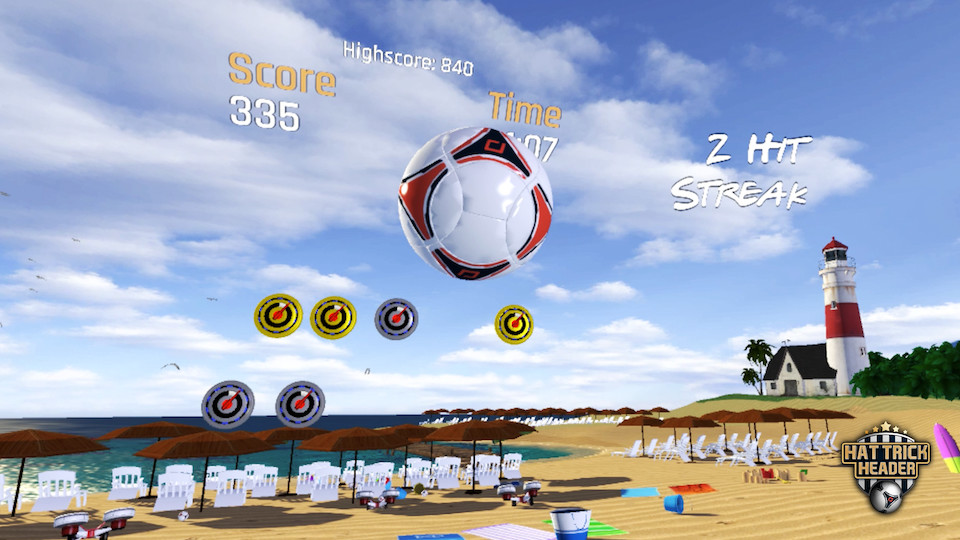
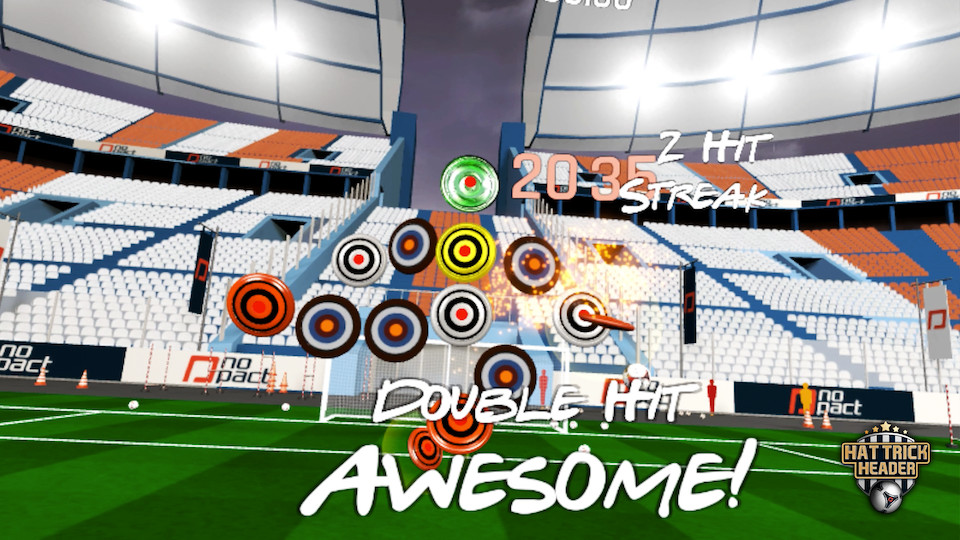
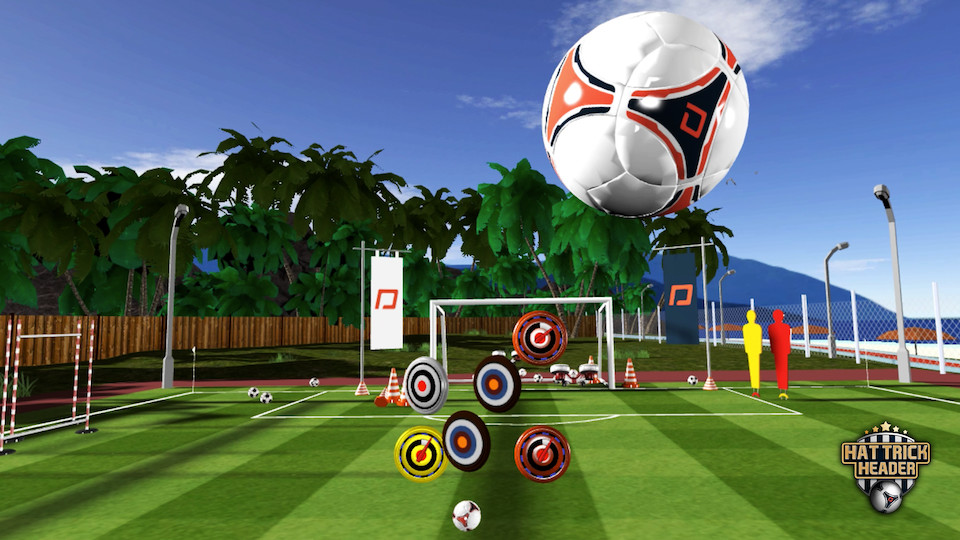
Hat Trick Header began as a VR game idea and playable prototype I developed at No-Pact during the Oculus DK2 period. The player headed incoming balls toward targets, controlling direction and power through the movement of the headset rather than a gamepad or hand controller.
The main question was simple: could you aim a football accurately enough using only your head for this to work as a game?
My contribution
A football-heading game built around the tracked movement of the player's head as the primary input.
The prototype tested how the position and movement of the headset could determine the direction and force of a header without relying on handheld controls.
Ball approach, contact, direction, and response were adjusted until the player could deliberately aim rather than simply trigger a collision.
The prototype made it quick to receive a ball, aim with the head, see where it went, and adjust the next attempt.
Later No-Pact production
After I left No-Pact, the studio continued the project and developed it into the fuller game released on Steam in 2016. That later production added the environments, interface, level content, multiplayer, achievements, and release material.
The released game retained the central head-controlled premise and expanded it into target-based levels across three locations, scoring and streak systems, and local hot-seat multiplayer. A 2017 update increased the level count from 18 to 45.
Gameplay and screenshots
 Oculus Rift gameplay by Hoopermation VR ->
Video / 2018
 HTC Vive gameplay by 30minVR ->
Independent work / WebGPU
A browser-based laboratory for soft bodies, local control, and movement.
Morphology-specific movement
I am building a simulation environment in which particle-and-spring bodies discover useful movement through their own morphology and local coordination.
It supports multiple lattices with different structures. Each lattice organism uses local sensing, short-lived state, and messages passed through its graph to find and apply a movement solution that fits its body, producing emergent locomotion.
The aim is for separate lattices to reach targets, change shape, and work through obstructions by finding their own solutions, then to observe how those solutions differ between morphologies.
Body authoring, live simulation, experiment control, and behavioral inspection are kept in the same environment so new forms and control approaches can be tested quickly.
Current spring-only navigation
The lattice compresses through the narrow opening, then follows and begins collecting a newly placed target path. Recorded 30 August 2026.
From authoring to a denser adversarial setup
A lower-particle lattice organism is assembled in the Body Editor and stamped into the live simulation. The recording then cuts to the crowded obstacle field, where it moves alongside several other organisms, including four-armed morphologies. Recorded 30 August 2026.
Distributed control
Particles and springs form the body, including its physical limits and the paths through which signals can travel.
Each part acts from nearby sensory input and short-lived internal state rather than a complete view of the body.
Bounded messages move through the spring graph, allowing coordination without a central movement script.
The controller may alter existing spring target lengths. It cannot push the body or steer it directly toward a target.
Each lattice forms its own neural network at runtime, shaped by the particles and spring links that make up its body. The network learns as the simulation runs and adapts to structural changes, including newly added connections and tears that break existing ones.
Each particle works from local observations, short-lived internal state and messages exchanged with connected neighbours. Using the available actions in a movement dictionary, it learns how to manipulate the spring links extending from it. These actions change the springs’ target lengths within the simulation’s physical limits.
After the simulation advances, predicted effects are compared with observed outcomes. Feedback from progress, stability and obstruction informs subsequent decisions, allowing the system to refine useful coordination and explore alternatives.
Movement emerges from these local actions interacting across the body and with its environment. Different lattice structures can therefore develop different ways of moving, deforming and working through obstacles.
Development path
The project began in Unity as an experiment in groups of self-connecting agents. Each agent carried the state and rules needed to connect with copies of itself, exchange messages, fill local pools, and expand or contract the spacing between linked copies.
Those local pools fed group votes. Navigation began to emerge from their combined decisions rather than from a single agent acting as a central controller.
I later restarted the work from scratch as a standalone browser project to shorten the experiment loop. Changes to the simulation, control model, tools, and diagnostics can be made together, focused experiments can run quickly, and their results can be inspected immediately.
A harness and API expose that loop to AI agents: they can load states, change experiment conditions, run tests, inspect runtime readbacks, capture results, and return to named checkpoints. The project is therefore both a simulator and an agent-operated research environment.
Early browser experiments combined spring deformation with an additional directional force. The current system removes that layer: navigation has to arise from local decisions passed through the body and expressed through changes to its existing springs. This makes morphology and coordination part of the movement solution, rather than treating the lattice as a shape carried toward a target.
Earlier assisted controller
A direct target-oriented helper force was still active in this run. It is included as development history, not as evidence for the current spring-only controller. Recorded 8 June 2026.
My contribution
Particle-and-spring physics, a simplified directional medium response, interaction tools, and the browser runtime used for experiments.
Node-local state, sensing, spring-linked communication, action traces, and the composition of changes across the body.
A local editor for drawing nodes and links, applying symmetry, saving named morphologies, and stamping specimens into the live simulation.
An API for loading states, changing conditions, running focused tests, inspecting runtime readbacks, capturing results, and returning to named checkpoints.
From authoring to behavior
An initial morphology is edited, stamped, and observed in the live simulation. A second iteration then repeats the authoring-to-runtime loop with a different body. Recorded 30 August 2026.
Current state
Different lattice morphologies can now produce successful target-directed movement. When a body encounters a passage it cannot cross directly, trial and error can lead it to movement and deformation patterns that solve the obstruction.
The next focus is coordinated, task-specific movement within a single lattice: selected particles will take on movement roles and work together so designated parts of the body can reach their assigned targets.
Independent product / Unity
A Unity tool that grew from direct shape editing into a broader UI and 3D scene system.
The project
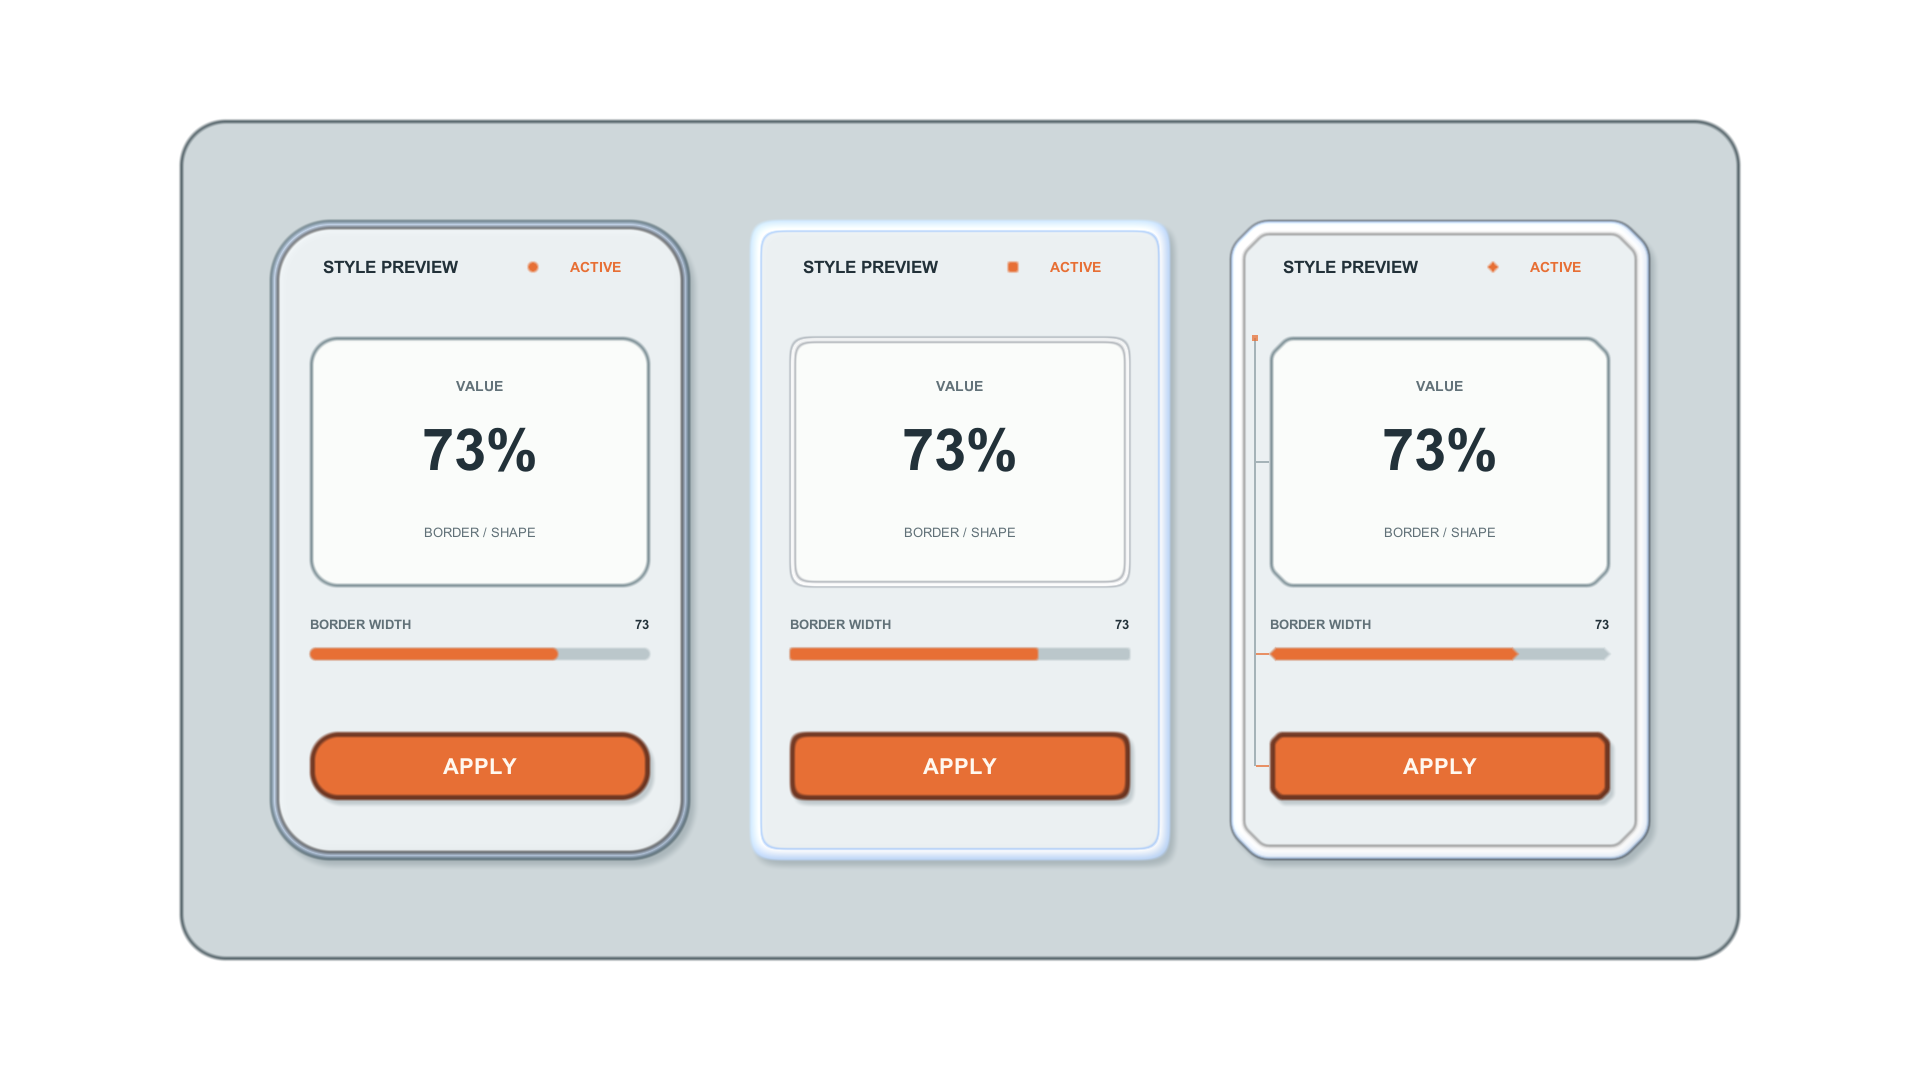
I began the project in 2025 with a procedural rounded rectangle that could be sized and adjusted directly in Unity's Scene view. The initial aim was practical: make a shape quick to build, tune, and reuse without preparing a separate sprite for every size or corner setting.
Using the tool kept exposing the next set of problems. The same shape needed to work in a Canvas and in a 3D scene, remain editable without losing authored values, respond to scripts and animation, and stay understandable as more appearance and workflow controls were added. The project developed by building those paths, testing them in working scenes, and revising the editor around what became difficult to use.
From editable shape to product
The first versions focused on procedural geometry and handles for size, corner radius, individual corners, and border width.
The shape expanded into world mesh, Canvas mesh, and Canvas SDF paths, with work to keep editing behavior and authored appearance consistent between them.
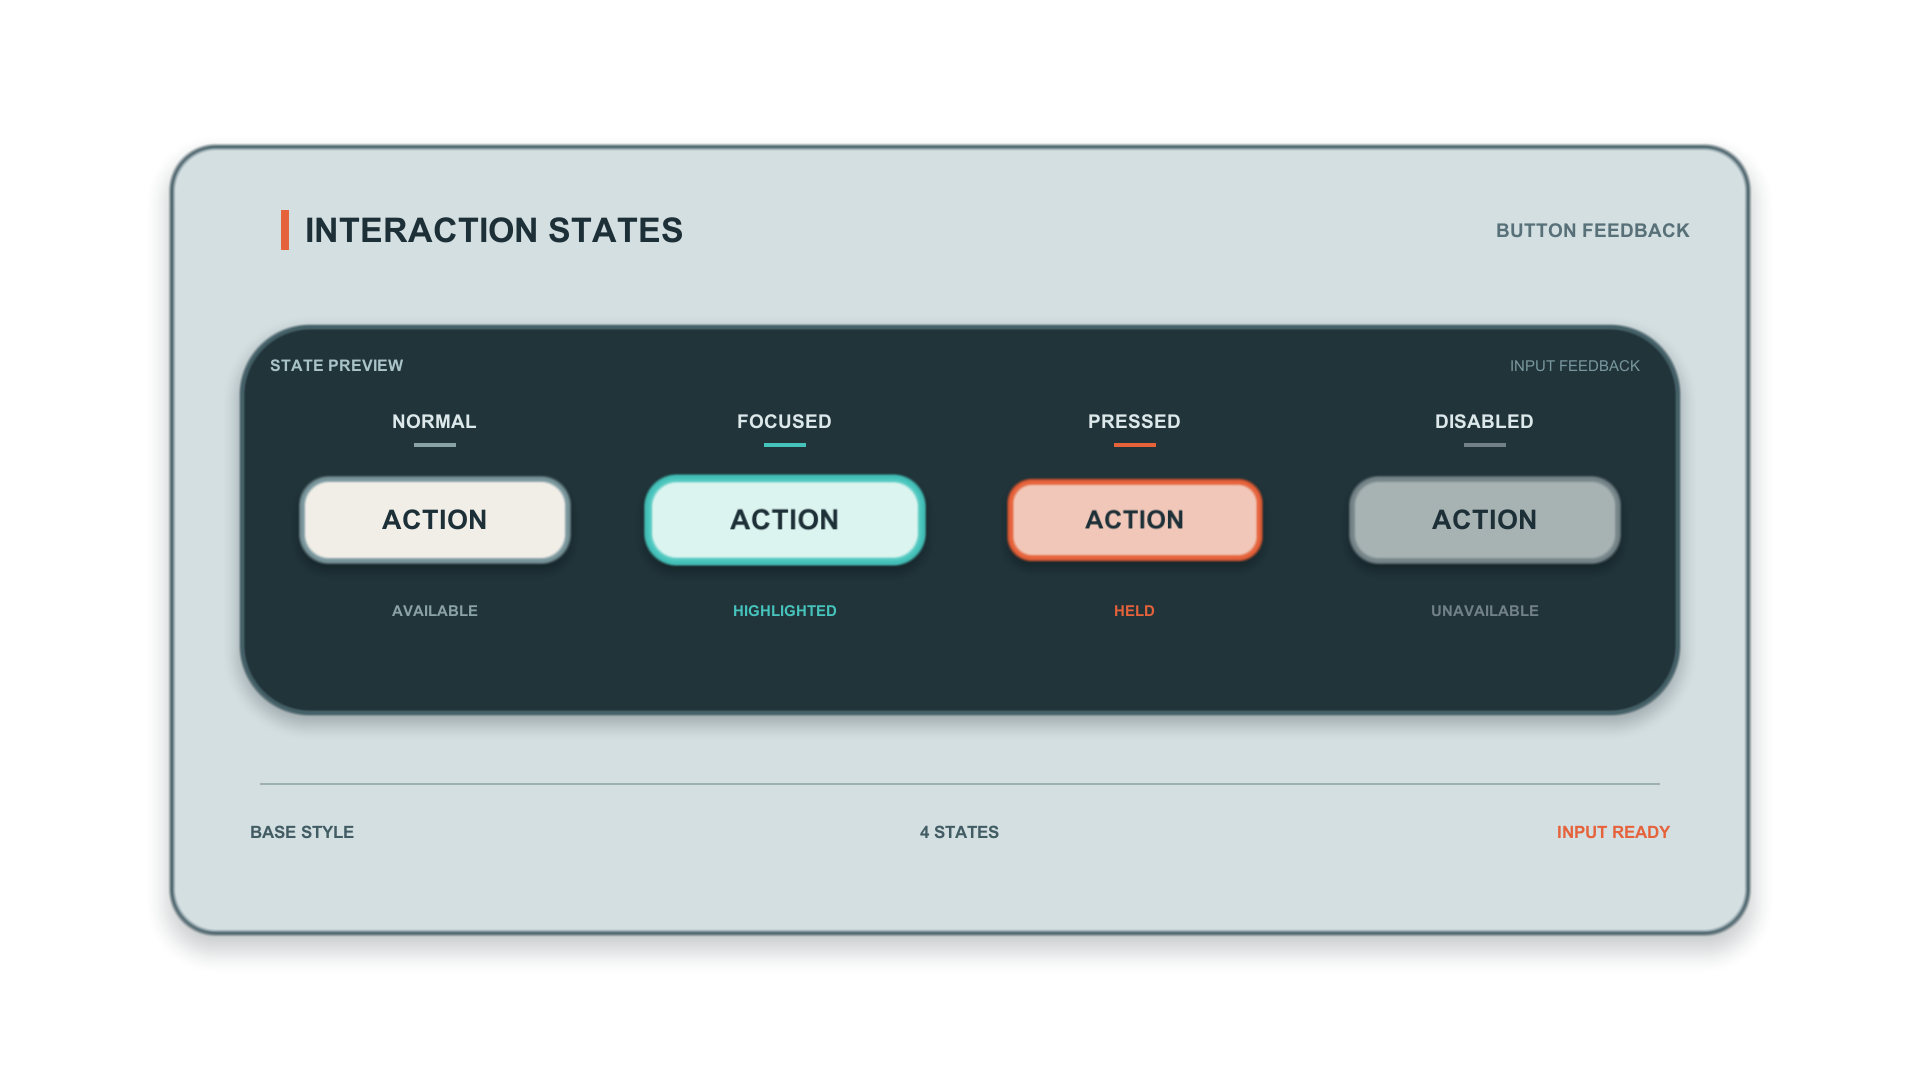
Runtime control, animation helpers, layout and button use, caching, and image export were added as working examples exposed needs beyond a static shape.
The current phase covers Inspector UX, Undo and resource ownership, example scenes, documentation, clean-package testing, and qualification across target Unity versions and render pipelines.
My contribution
Procedural mesh generation, Canvas SDF rendering, shaders, corner profiles, borders, fills, gradients, textures, transparency, and rendering-path behavior.
Scene handles, custom Inspectors, size and corner editing, conversion between rendering paths, material ownership, multi-edit behavior, and Undo/Redo workflows.
Script and animation control, buttons and layout helpers, runtime handles, cache workflows, generated collision, and bounded PNG or PSD output tools.
Example and stress-test scenes, user-facing documentation, visual capture workflows, compatibility testing, package cleanup, and Asset Store release preparation.
Product information and documentation
Company work / Medical visualization
Medical visualization, interactive 3D systems, and patient-specific design work.
Company
Orbycra Bilişim Teknolojileri A.Ş. was founded by Giray Ötken, Başak Çakmak, and Ahmet Tolgay Akıncı through the TÜBİTAK 1812 BiGG support programme. The company is based at İTÜ ARI Teknokent and develops medical visualization and patient-specific design systems.
The work has followed two main project lines. GraftEngine focused on AI-assisted graft, mold, and guide design from medical imaging data. The current DICOM Viewer direction focuses on interactive, non-clinical volumetric visualization and reusable visual workspaces.
Co-founders
Project lead, software developer, and designer. My work covers the Unity applications, medical visualization and interaction systems, patient-specific design workflows, technical development, and project reporting.
Software developer and user interface designer, with a background in architecture, computational design, XR development, and academic research. For GraftEngine, she worked on planning and designing the 3D model-completion AI system, including its AI architecture, training approach, and model training.
Neurosurgeon and medical device developer. He provides the clinical and surgical domain expertise for cranial grafts, spinal guide apparatuses, patient-specific devices, and the medical relevance of the work.
Current direction
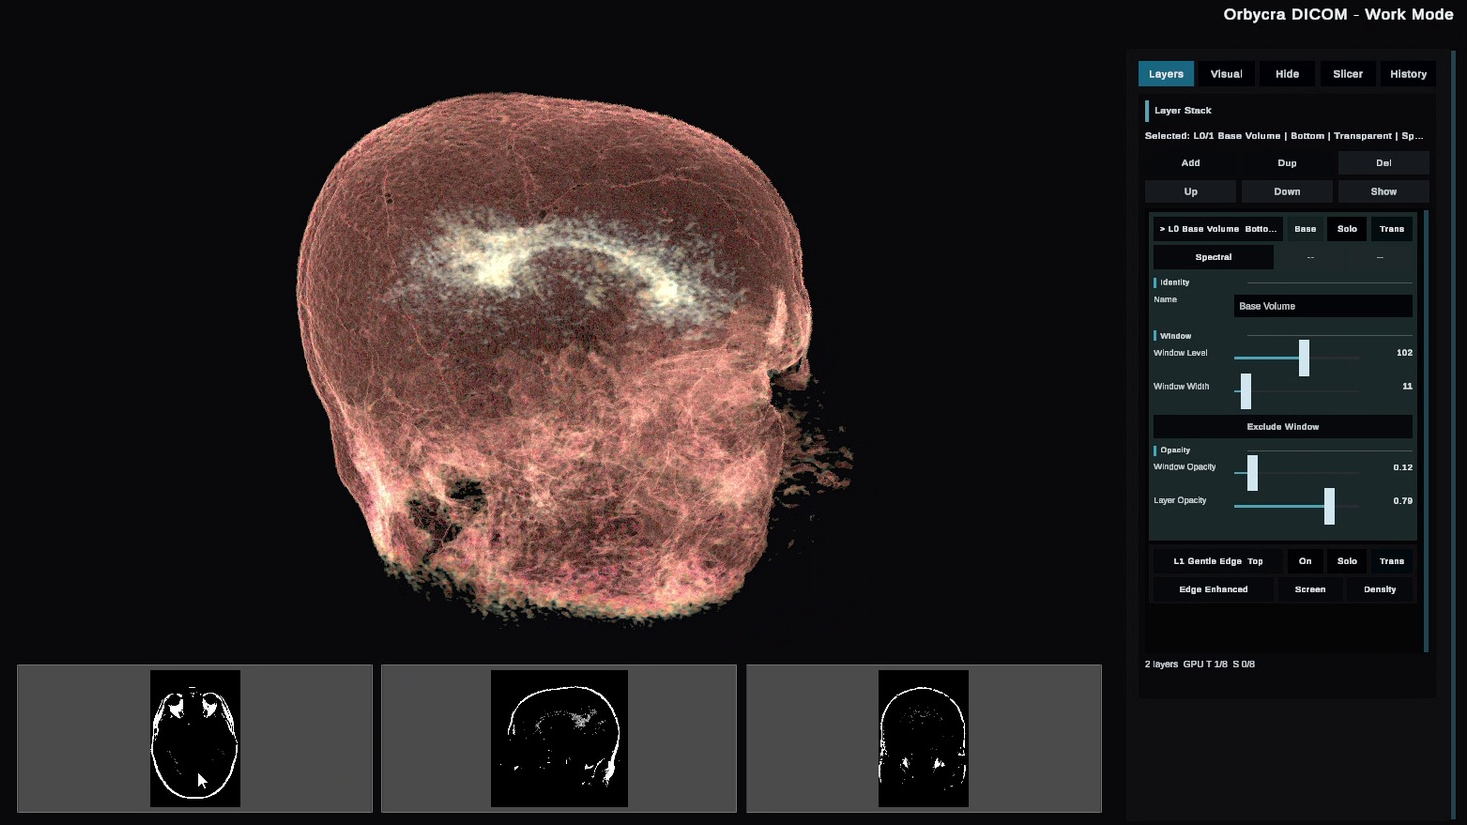
The Orbycra DICOM Viewer is being developed as a non-clinical volumetric visualization workspace. The desktop version loads DICOM series and visualizes scan intensity data as an interactive 3D volume inside a Unity application.
The current workspace is organized around visual layers, reusable states, inspection tools, and reversible operations rather than a single fixed rendering preset.
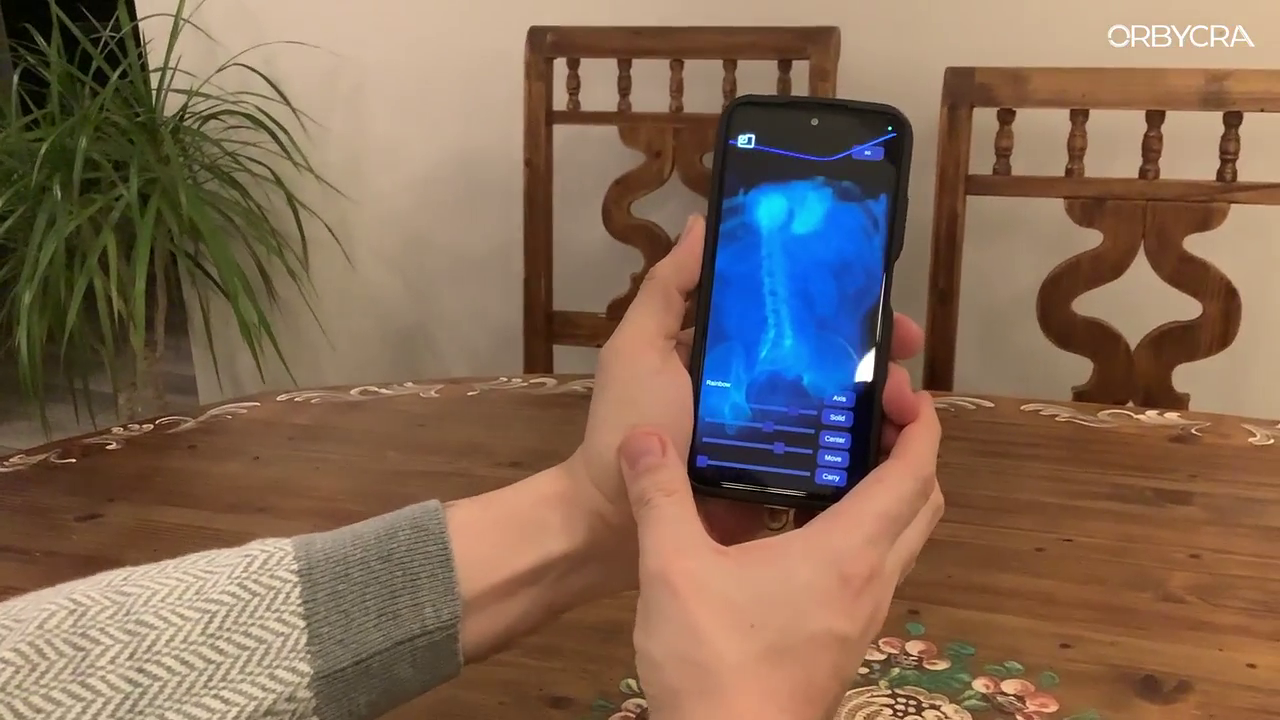
Earlier mobile and XR prototypes used a custom HLSL/URP ray-marching shader designed for interactive volumetric rendering on mobile-class GPUs. Empty-space skipping and dynamic sampling reduced unnecessary volume samples while retaining windowing, opacity, and transfer-function control.
DICOM series loading, 3D texture preparation, ray-marched volume rendering, visible intensity ranges, window level/width, and transparent or solid results.
Base and derived visual layers with visibility, solo, ordering, opacity, density, color, blend, and mask settings.
Axis views, slicer tools, filters, masks, voxel editing, density exclusion, and app-level undo/redo for reversible exploration.
Recipes for visual setups, sessions for application state, and operation history without treating raw patient series as part of the saved visual preset.
TÜBİTAK 1812 / BiGG project
GraftEngine was Orbycra's earlier project line for AI-assisted patient-specific grafts, graft molds, and related surgical-device design workflows. The supported project ran from 2024 to 2025 and combined medical image processing, machine-learning experiments, 3D modeling, and physical prototyping.
The cranial reconstruction work began with pro bono patient-specific design and manufacturing by Orbycra. For individual cases, Orbycra designed the cranial grafts and produced their molds at no cost; co-founder Assoc. Prof. Dr. Ahmet Tolgay Akıncı then used the resulting molds in surgery. GraftEngine grew from the effort to make parts of this case-by-case workflow more repeatable through medical-image processing, 3D design tools, and assisted geometry generation.
The project records include cranial graft and mold workflows, bone-defect datasets and completion experiments, cervical guide apparatus prototypes, and printed anatomy used for fit and design checks.
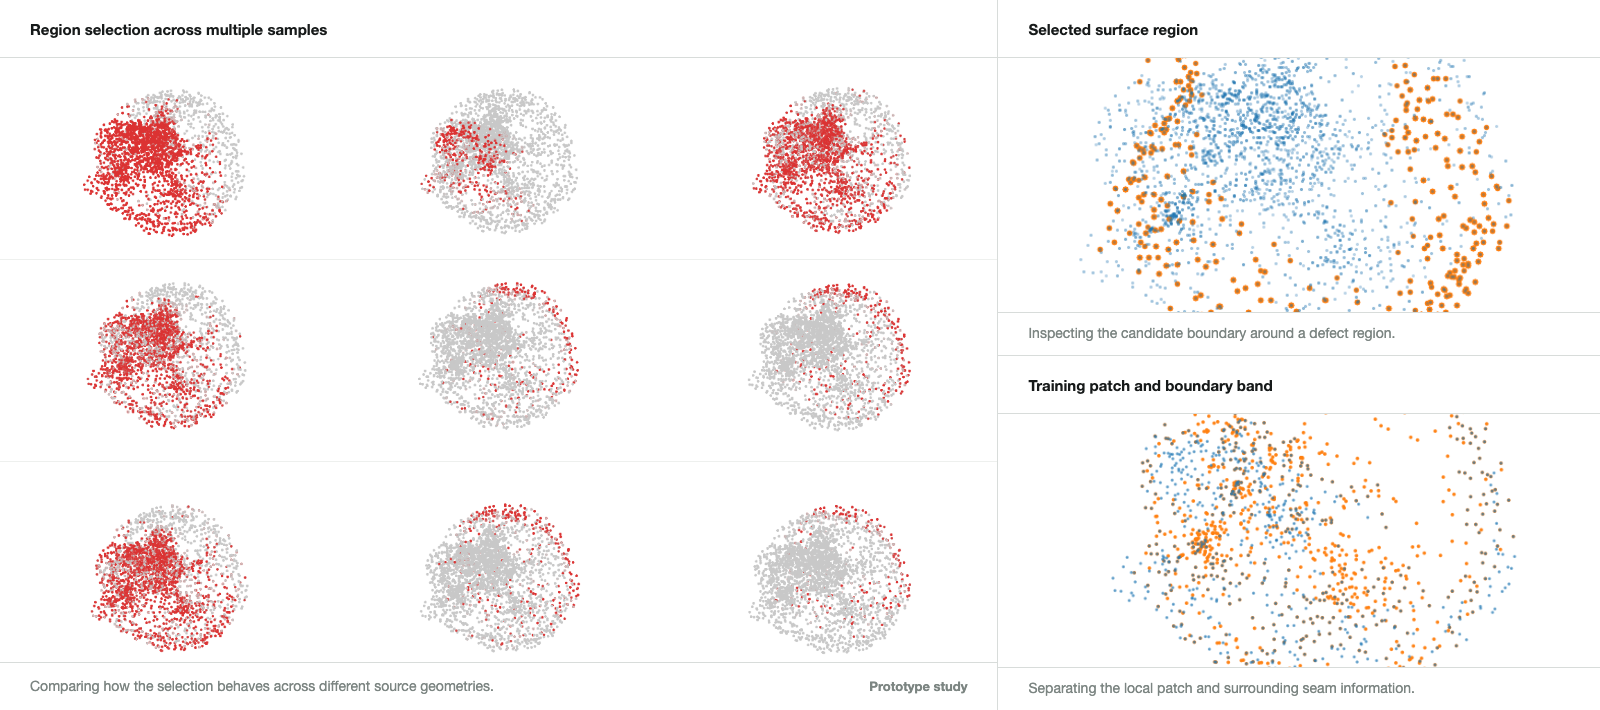
Bone datasets, synthetic defect generation, labeling, Mask R-CNN detection work, and PyTorch-based 3D completion experiments.
Segmentation, reconstruction, density-based model generation, mesh repair, and conversion into editable patient-specific geometry.
Cranial defect completion, graft-form development, and negative-mold workflows for physical production.
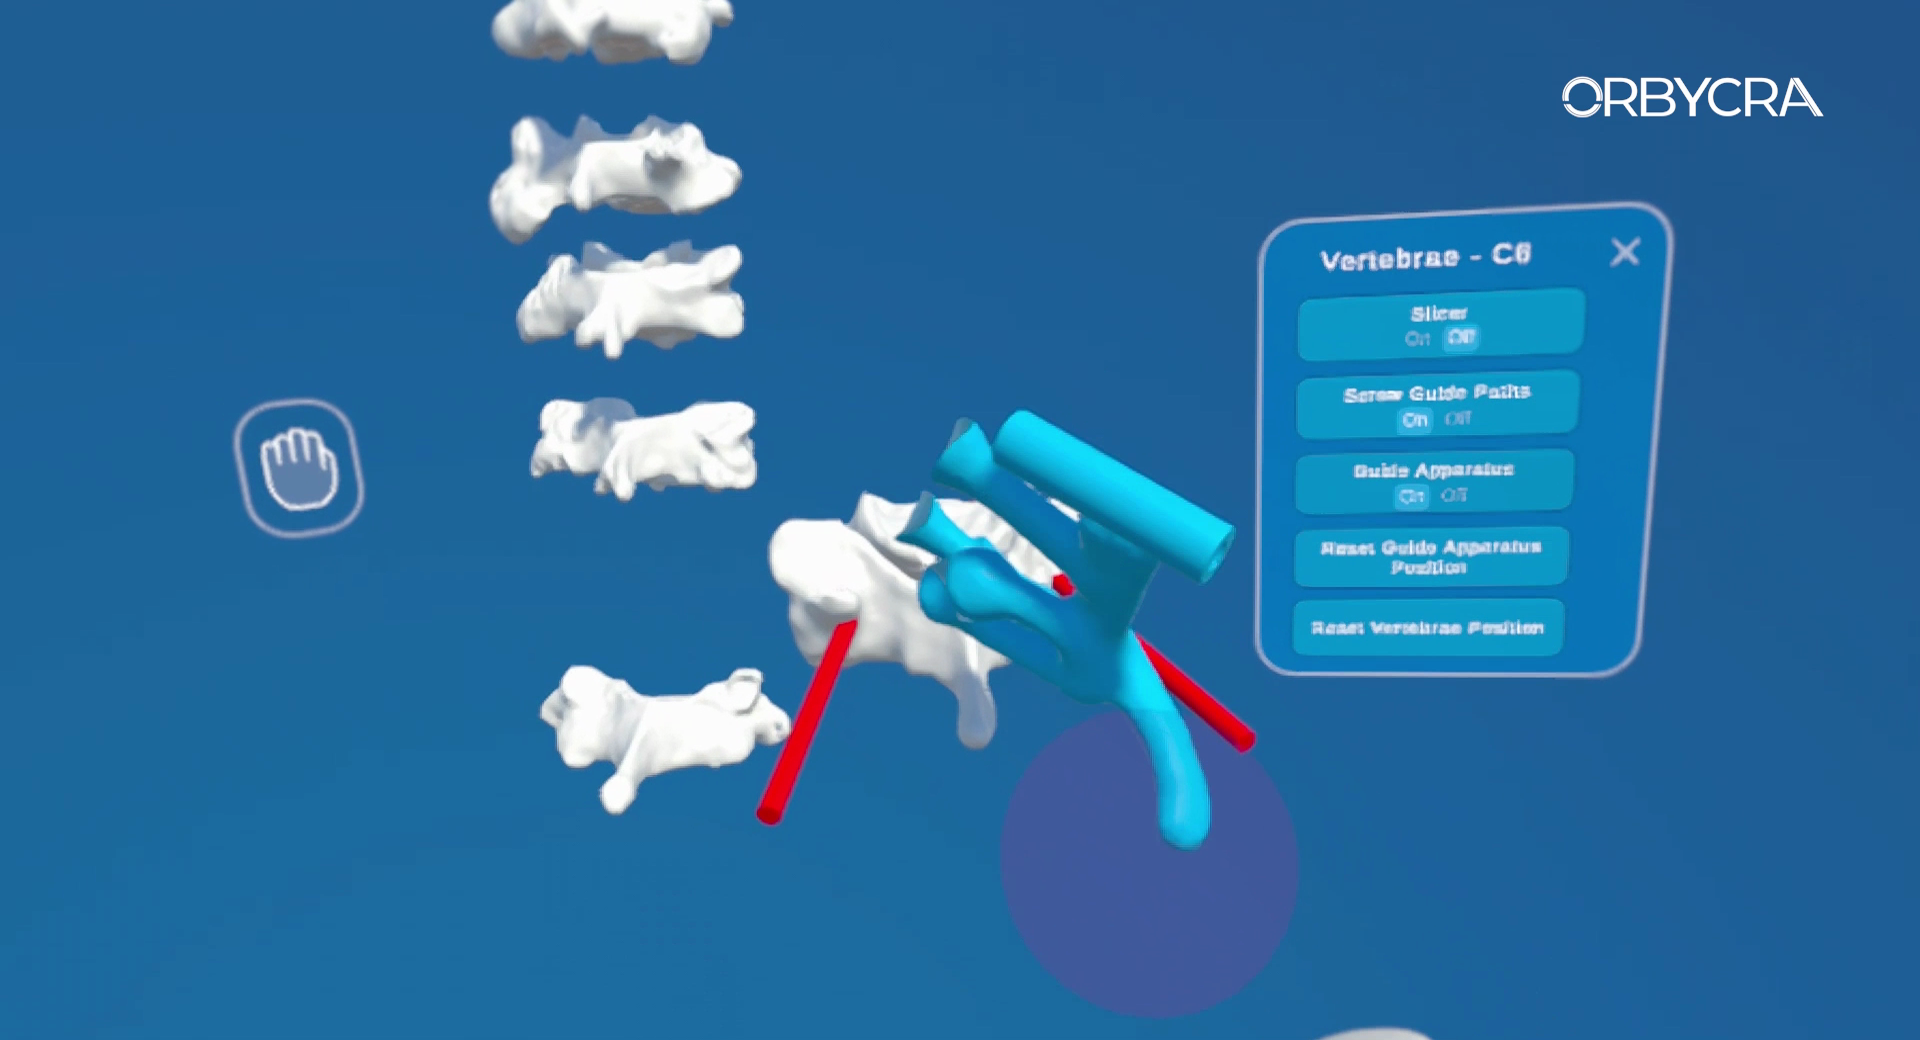
Cervical and spinal guide design using DICOM-derived anatomy, parametric fitting, printed vertebra models, and PLA/FDM prototypes.
My contribution
Unity/C# application work, DICOM data handling, GPU volume rendering, shader development, layer architecture, state systems, and desktop interaction tools.
Viewer controls, inspection workflows, visual presets, desktop UI structure, reversible operations, and the translation of technical functions into usable tools.
DICOM-to-model workflows, cranial graft molds, guide geometry, Maya and ZBrush work, mesh preparation, and 3D-printable prototypes.
Technical architecture, implementation, testing, reporting, grant and Teknokent project work, and coordination with clinical and computational-design collaborators.
Personal system / Local-first
A graph-backed work system for project context, research, decisions, tasks, and agent-assisted workflows.
The system
I built GTaskSystem to keep ongoing work inspectable across different projects, documents, research records, decisions, and conversations with coding agents. It is a local working system rather than a hosted task-management product.
A compact node-edge graph stored in SQLite holds tasks and related records. Small command-line tools retrieve the part of the graph needed for a question, a decision, or a work session. Each source project remains authoritative for its own code, documentation, and detailed state.
Why I started it
This is not a problem unique to GTaskSystem. Task managers, personal knowledge tools, knowledge graphs, and agent-memory systems all address parts of it. My version began from a practical situation: active work was spread across repositories, documents, conversations, research, and different time scales.
A project can be present in code, notes, chat history, research, and external obligations at the same time. Reconstructing the whole situation repeatedly is slow.
A flat task title rarely preserves why the work exists, what it depends on, which decision produced it, or what evidence is already available.
Coding agents need enough context to continue correctly, but reading every document and history file is slow, noisy, and sometimes unsafe.
A central overview is useful, but it should not duplicate or replace the implementation truth held inside each project.
Current model
Tasks, projects, decisions, research, evidence, and people remain compact records instead of becoming one large project document.
Directional links record dependencies, ownership, evidence, history, and context that a flat list would discard.
Higher-level nodes and hierarchical links lead from a compact route to narrower context, evidence, and finally detailed source documents. Agents stop at the first layer that answers the question instead of loading the full history.
The system supplies facts, routes, and constraints. A person or agent still interprets them and decides what the situation means.
Current performance
GTaskSystem does not yet have a formal benchmark. The useful evidence is continued use: the graph has grown beyond 1,600 nodes and 5,000 links while supporting active software, game, product, research, administrative, and career work.
It has been most useful as a context-recovery and coordination layer rather than as an automatic planner.
Compact queries and packets can recover the relevant tasks, dependencies, evidence, and source routes without loading the full system.
Research artifacts remain connected to the task or decision that produced them, making earlier findings easier to reuse and inspect.
Project-local agents can exchange compact status and result notes through a central ledger while their source repositories remain independent.
The same graph can produce focused views for what is next, what is waiting, what changed, and which area needs deeper inspection.
When a question needs explicit criteria and tradeoffs, GTaskSystem can supply the relevant context to WeightedAnalysis, while the decision model remains separately editable.
What remains unresolved
The system has not solved prioritization or memory automatically. Its quality still depends on what gets captured, old relationships need maintenance, and several interfaces remain working prototypes rather than a finished application.
The graph is useful when it reduces search and reconstruction. It becomes overhead when the model grows faster than actual use. The current aim is therefore limited: preserve enough structure to recover context, inspect why something exists, and continue work without rebuilding the whole picture each time.
I continue to develop GTaskSystem through daily use and plan to release a public version once the core model and workflows are stable enough to be useful outside my own setup.
Personal application / Local-first
A decision workbench for comparing options through explicit criteria, weights, scores, evidence, uncertainty, and stages.
The application
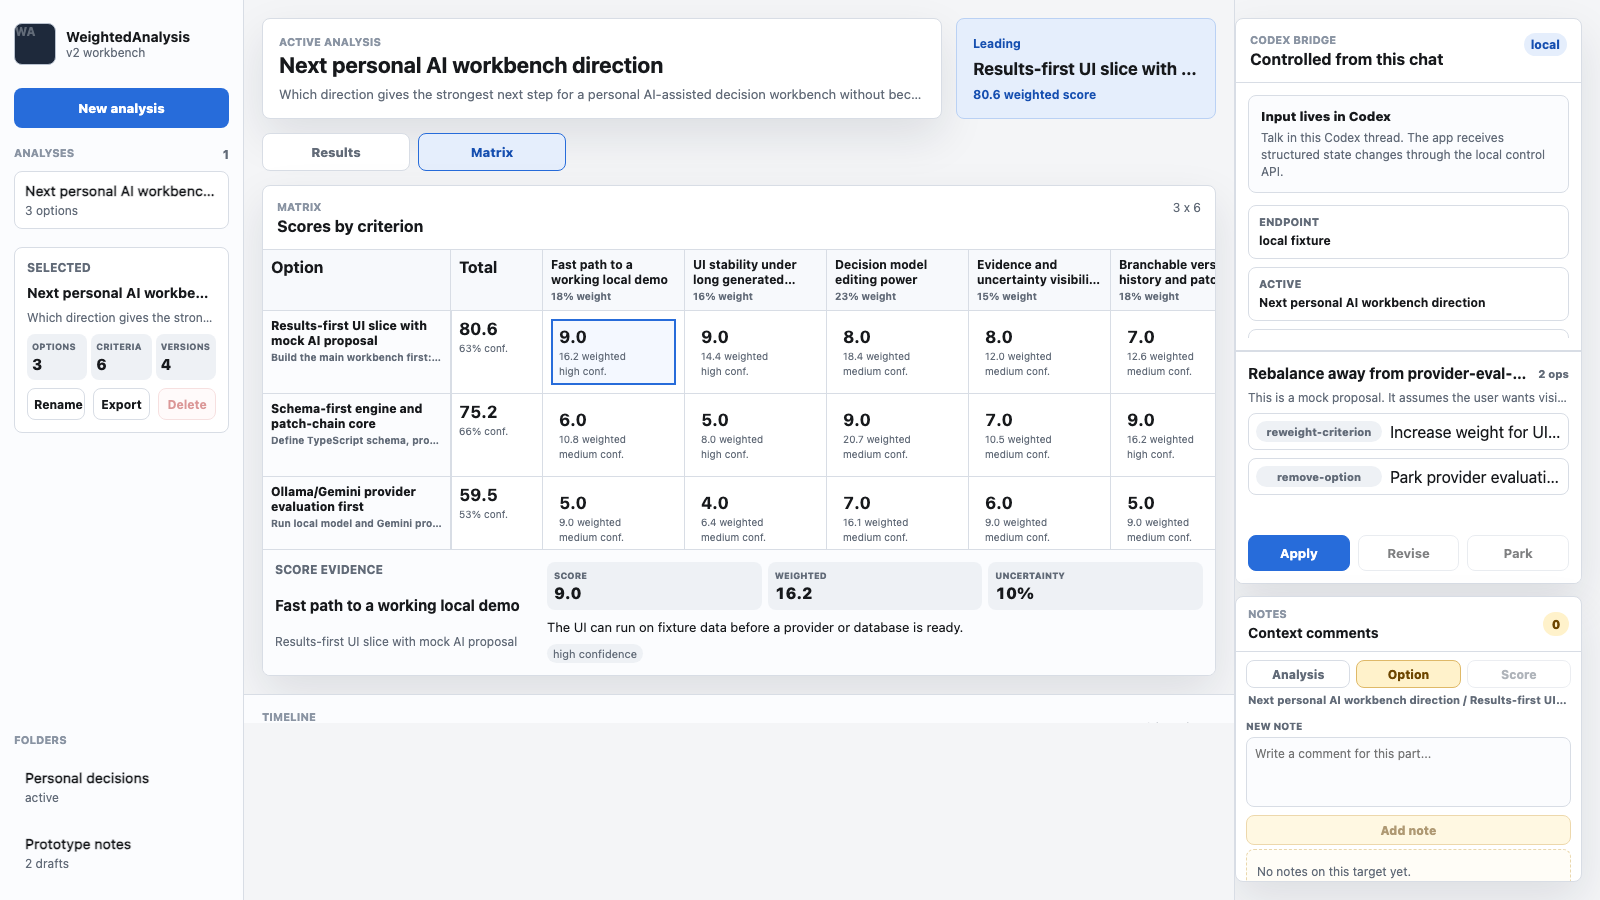
I built WeightedAnalysis for decisions that become difficult to inspect once they are reduced to a single recommendation or a spreadsheet snapshot. Each analysis keeps the question, options, criteria, weights, scores, rationales, and confidence in one editable model.
The user owns the model. Codex can create or revise an analysis through a local control interface, but the accepted state remains visible, editable, and recalculable. GTaskSystem can provide the relevant project context; WeightedAnalysis handles the decision model itself.
Structure
Criteria are named so a higher score always means a better result. Their weights remain editable, allowing the ranking to change when priorities change.
Each option is scored against the same criteria. The application calculates weighted totals and keeps the complete matrix available for inspection.
A score can include its rationale, confidence, uncertainty, and missing information instead of appearing as an unexplained number.
One decision can be divided into ordered stages with different options and criteria. Accepted changes preserve earlier versions rather than silently replacing them.
Working interface
The main view starts with the current ranking and the weights that produced it. The full matrix is a separate inspectable view, where individual scores can be selected to reveal their evidence and uncertainty.
Structured proposals from Codex are shown before they change the accepted analysis. Manual weight edits and accepted proposals use the same scoring and state-mutation logic.
Current use
The current library contains working analyses for project time allocation, release preparation, creative-production planning, research targets, purchasing comparisons, and staged experiment selection.
The useful result is not a claim that the highest score is objectively correct. It is the ability to see which assumptions produced that result, adjust them, and return to the same decision without reconstructing the whole argument.
Current state
The application is a working local v2 prototype. Results, matrix inspection, editable weights, score evidence, JSON import and export, staged analyses, proposals, and version snapshots are implemented.
It is not a decision oracle, and it does not yet have a formal benchmark. Generated starting points still need review, the current persistence layer is JSON-based, and deeper comparison between branches and versions remains under development.